Genetic evaluation with known variance components in sommer
sommer development team
2026-10-06
Source:vignettes/sommer.genetic.evaluation.Rmd
sommer.genetic.evaluation.RmdOverview
Routine genetic evaluations predict breeding values for very large populations with variance components that are considered known. They were estimated earlier, usually by REML on a smaller but representative subset of the data. The expensive part is then not variance-component estimation but solving the mixed-model equations (MME)
once, for possibly millions of animals.
mmes(..., solveOnly=TRUE) does exactly that. It uses the
same formula interface as a REML fit but never estimates variances,
never computes a likelihood, and never assembles
.
Instead, it iterates on the data with a preconditioned conjugate
gradient (PCG):
- each product is computed as plus the prior term , where and holds the coefficients of as levels traits;
- is applied block by block (one block per record, or per animal for multi-trait residuals);
- the preconditioner is block-Jacobi: one dense block for the fixed effects and one block per animal coupling its traits.
Memory and time per iteration are therefore linear in the number of records, pedigree entries, and animals.
This vignette walks through the usual two-step workflow:
- simulate a two-trait population with a pedigree;
- estimate and by REML on a small subset of herds;
- use those estimates to evaluate the whole population, including young animals without records.
Simulated population
Pedigree and relationship inverse
We simulate six discrete generations of 3000 animals each, with 60 sires and 1500 dams used per generation. Animals of the last generation are young selection candidates without records of their own.
simulate_pedigree <- function(nGen, perGen, nSires){
  n <- nGen * perGen
  gen <- rep(seq_len(nGen), each=perGen)
  male <- rep(c(TRUE, FALSE), length.out=n)
  sire <- dam <- rep(NA_integer_, n)
  for(g in 2:nGen){
    prev <- which(gen == g - 1L)
    cur <- which(gen == g)
    sires <- sample(prev[male[prev]], nSires)
    sire[cur] <- sample(sires, length(cur), replace=TRUE)
    dam[cur] <- sample(prev[!male[prev]], length(cur), replace=TRUE)
  }
  data.frame(index=seq_len(n), id=paste0("A", seq_len(n)), sire=sire, dam=dam,
             gen=gen)
}

ped <- simulate_pedigree(nGen=6, perGen=3000, nSires=60)
head(ped[ped$gen == 2, ])
## index id sire dam gen
## 3001 3001 A3001 399 1774 2
## 3002 3002 A3002 2677 2062 2
## 3003 3003 A3003 1637 2734 2
## 3004 3004 A3004 255 2080 2
## 3005 3005 A3005 1783 1008 2
## 3006 3006 A3006 399 2556 2The inverse of the numerator relationship matrix follows Henderson’s
rules,
,
where
and
holds
for each known parent. To keep the code short, the within-family
variances in
ignore inbreeding, which is negligible over six generations in a
population of this size. The breeding values below are simulated from
the same model. In practice,
would come from a pedigree package, and a 3-column (row, column, value)
table is also accepted as Gu.
pedigree_ainv <- function(ped){
  n <- nrow(ped)
  hasSire <- !is.na(ped$sire)
  hasDam <- !is.na(ped$dam)
  P <- sparseMatrix(i=c(which(hasSire), which(hasDam)),
                    j=c(ped$sire[hasSire], ped$dam[hasDam]),
                    x=0.5, dims=c(n, n))
  Tm <- Diagonal(n) - P
  dinv <- 1 / (1 - 0.25 * (hasSire + hasDam))
  Ainv <- forceSymmetric(crossprod(Tm, Diagonal(x=dinv) %*% Tm))
  dimnames(Ainv) <- list(ped$id, ped$id)
  attr(Ainv, "inverse") <- TRUE
  Ainv
}
Breeding values and phenotypes
Two traits, think of weaning weight and yearling weight, have the following genetic () and residual () covariance matrices:
G0 <- matrix(c(0.30, 0.23,
               0.23, 0.50), 2, dimnames=list(c("y1","y2"), c("y1","y2")))
R0 <- matrix(c(0.70, 0.24,
               0.24, 0.90), 2, dimnames=list(c("y1","y2"), c("y1","y2")))
cov2cor(G0)[1, 2]   # genetic correlation
## [1] 0.5938574## y1 y2
## 0.3000000 0.3571429Breeding values are the parent average plus a Mendelian sampling term, simulated generation by generation. Records of generations 1 to 5 belong to 300 herds (contemporary groups), whose effects are fixed in the model. The second trait is missing for 30% of the animals, as happens when animals leave the herd before the second measurement.
n <- nrow(ped)
bv <- matrix(0, n, 2, dimnames=list(ped$id, c("y1", "y2")))
dvar <- 1 - 0.25 * ((!is.na(ped$sire)) + (!is.na(ped$dam)))
mendelian <- matrix(rnorm(n * 2), n) %*% chol(G0)
for(g in sort(unique(ped$gen))){
  cur <- which(ped$gen == g)
  pa <- if(g == 1) 0 else 0.5 * (bv[ped$sire[cur], ] + bv[ped$dam[cur], ])
  bv[cur, ] <- pa + sqrt(dvar[cur]) * mendelian[cur, ]
}

recorded <- ped[ped$gen < 6, ]
nHerd <- 300
recorded$herd <- factor(sample(seq_len(nHerd), nrow(recorded), replace=TRUE))
herdEffect <- matrix(rnorm(nHerd * 2, sd=c(1, 1.5)), nHerd, byrow=TRUE)
errors <- matrix(rnorm(nrow(recorded) * 2), ncol=2) %*% chol(R0)
recorded$y1 <- 10 + herdEffect[recorded$herd, 1] + bv[recorded$index, 1] + errors[, 1]
recorded$y2 <- 20 + herdEffect[recorded$herd, 2] + bv[recorded$index, 2] + errors[, 2]
recorded$y2[sample(nrow(recorded), round(0.3 * nrow(recorded)))] <- NA
dim(recorded)
## [1] 15000 8Multi-trait models in mmes() use the long format.
stackTraits() creates one row per animal and trait, plus a
record key that tells the residual structure which records
belong to the same animal. Rows with missing trait values are dropped by
mmes() automatically.
pheno <- recorded[, c("id", "herd", "gen", "y1", "y2")]
long <- stackTraits(pheno, traits=c("y1", "y2"))
head(long)
## id herd gen record trait value
## 1 A1 291 1 r1 y1 9.038739
## 2 A2 30 1 r2 y1 11.272932
## 3 A3 30 1 r3 y1 9.065007
## 4 A4 156 1 r4 y1 10.776899
## 5 A5 140 1 r5 y1 11.993836
## 6 A6 123 1 r6 y1 7.665852Step 1: REML on a subset of herds
Variance components are estimated on 60 of the 300 herds (about 20% of the records). The relationship inverse is built from the sub-pedigree of those animals and all their ancestors, so the REML problem stays small.
trace_pedigree <- function(ped, index){
  keep <- rep(FALSE, nrow(ped))
  todo <- index
  while(length(todo)){
    keep[todo] <- TRUE
    parents <- c(ped$sire[todo], ped$dam[todo])
    todo <- unique(parents[!is.na(parents) & !keep[parents]])
  }
  sub <- ped[keep, ]
  sub$sire <- match(sub$sire, sub$index)
  sub$dam <- match(sub$dam, sub$index)
  sub
}

pilotHerds <- levels(long$herd)[1:60]
pilot <- droplevels(long[long$herd %in% pilotHerds, ])
pilotPed <- trace_pedigree(ped, recorded$index[recorded$herd %in% pilotHerds])
c(records=nrow(pilot), animals=length(unique(pilot$id)), pedigree=nrow(pilotPed))
## records animals pedigree
## 5918 2959 5496The model has trait-specific herd effects, an unstructured genetic
covariance between traits with the relationship inverse as
Gu, and an unstructured residual covariance between the two
records of the same animal.
Ainv <- pedigree_ainv(pilotPed)
timeReml <- system.time(
  reml <- mmes(value ~ trait + trait:herd,
               random = ~ vsm(usm(trait), ism(id), Gu=Ainv),
               rcov = ~ vsm(usm(trait), ism(record)),
               data=pilot, verbose=FALSE)
)
## Adding 2537 additional Gu levels to the main-effect model matrix: A10, A12, A18, A20, A22, A26, A28, A32, A42, A50 ...## Solver selected: ldlt
timeReml[["elapsed"]]## [1] 8.395The estimated covariance matrices are close to the simulated ones, given the size of the pilot data:
G0hat <- covmatrix_mmes(reml, 1)
R0hat <- covmatrix_mmes(reml, 2)
round(G0hat$covariance, 3)
## y1 y2
## y1 0.355 0.282
## y2 0.282 0.508
round(G0hat$covariance.se, 3)## y1 y2
## y1 0.051 0.051
## y2 0.051 0.083
round(R0hat$covariance, 3)## y1 y2
## y1 0.684 0.257
## y2 0.257 0.913Step 2: evaluation of the whole population
The whole population is now evaluated with these variance components.
The model formula is unchanged; only the data and the relationship
inverse change. Because the relationship inverse is again called
Ainv, the term labels match those of reml, and
the fitted object can be passed directly as covPar. Its
final working-scale estimates are used exactly.
Ainv <- pedigree_ainv(ped)
timeEval <- system.time(
  ebv <- mmes(value ~ trait + trait:herd,
              random = ~ vsm(usm(trait), ism(id), Gu=Ainv),
              rcov = ~ vsm(usm(trait), ism(record)),
              data=long, solveOnly=TRUE, covPar=reml, verbose=FALSE)
)
## Adding 3000 additional Gu levels to the main-effect model matrix: A15001, A15002, A15003, A15004, A15005, A15006, A15007, A15008, A15009, A15010 ...## Engine selected: known-covariance PCG (solveOnly=TRUE)
timeEval[["elapsed"]]## [1] 0.233
ebv## Known-covariance mixed-model solution (mmes, solveOnly=TRUE)
## Equations: 36600 fixed: 600 random: 36000 records: 25500
## PCG converged in 82 iterations; relative residual 9.81e-09
## Variance parameters used:
## term parameter value
## vsm(usm(trait), ism(id), Gu = Ainv) sigma2 0.3552469
## vsm(usm(trait), ism(id), Gu = Ainv) usm(trait):chol[y2,y1] 0.7947331
## vsm(usm(trait), ism(id), Gu = Ainv) usm(trait):chol_diag[y2] 0.8939969
## vsm(usm(trait), ism(record)) sigma2 0.6839755
## vsm(usm(trait), ism(record)) usm(trait):chol[y2,y1] 0.3764455
## vsm(usm(trait), ism(record)) usm(trait):chol_diag[y2] 1.0920492The object of class mmesSolve contains the solutions
(b, u, bu, uList),
fitted values and residuals, the covariance
matrices that were used (theta), the parameters that were
used in natural scale (vcParams), and the solver
diagnostics (pcg). Animals in Gu without
records, here all of generation 6, are added automatically and receive
pedigree-based predictions.
ebv$pcg[c("iterations", "relres", "converged", "setupSeconds", "solveSeconds")]## $iterations
## [1] 82
##
## $relres
## [1] 9.811506e-09
##
## $converged
## [1] TRUE
##
## $setupSeconds
## [1] 0.0186952
##
## $solveSeconds
## [1] 0.09254899
plot(log10(ebv$pcg$history), type="l", xlab="PCG iteration",
     ylab="log10 relative residual")
abline(h=log10(1e-8), lty=2)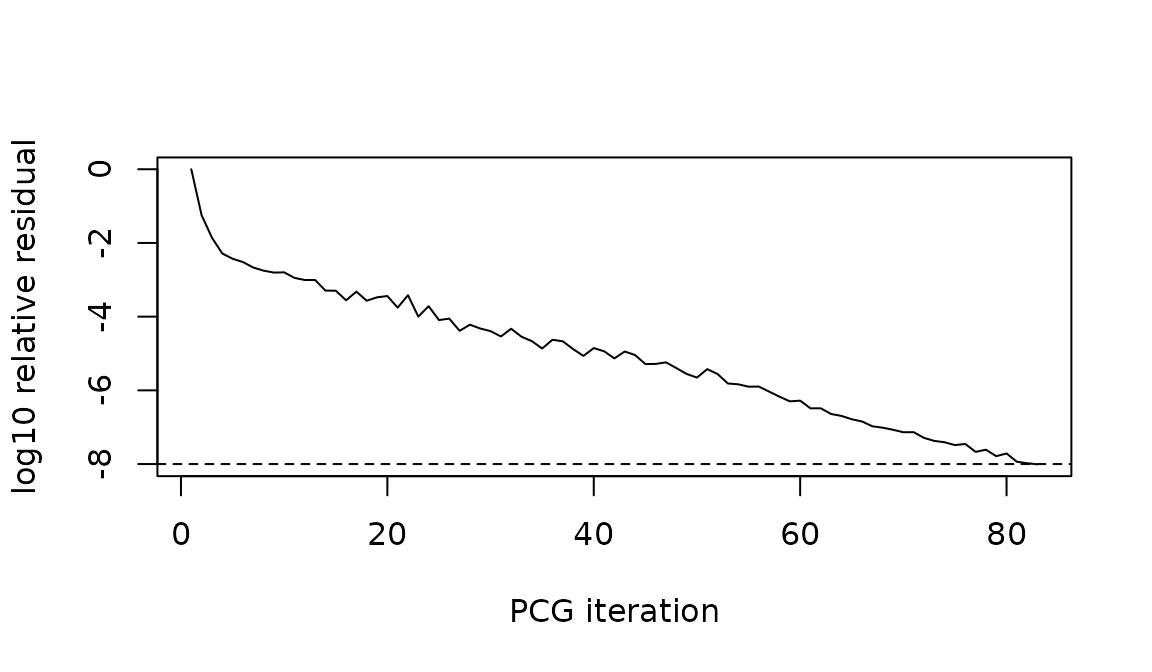
Accuracy of the predicted breeding values
The correlation between predicted and true breeding values measures the realized accuracy. Animals with records are predicted more accurately than the young candidates, whose predictions rely on parent averages only. The second trait benefits from the genetic correlation with the first, which is recorded for every animal.
u <- ebv$uList[[1]][ped$id, ]
accuracy <- function(rows) diag(cor(u[rows, ], bv[rows, ]))
rbind(recorded = accuracy(ped$gen < 6),
      candidates = accuracy(ped$gen == 6))
## y1 y2
## recorded 0.7061707 0.6935276
## candidates 0.4958470 0.4984512Selection decisions use the predicted breeding values of the candidates, e.g. with an index that weights both traits equally:
candidates <- ped$id[ped$gen == 6]
index <- u[candidates, "y1"] + u[candidates, "y2"]
top <- head(sort(index, decreasing=TRUE), 5)
data.frame(id=names(top), index=round(top, 3),
           trueIndex=round(rowSums(bv[names(top), ]), 3))
## id index trueIndex
## A17351 A17351 1.614 0.813
## A16532 A16532 1.516 2.407
## A16176 A16176 1.389 0.738
## A15992 A15992 1.384 0.050
## A15403 A15403 1.382 1.287Other ways to give the variance components
covPar accepts other inputs besides a fitted object:
- a list of covariance matrices, one per term in formula order (random
terms, then the residual), for terms built from
ism(),dsm()andusm(). This is the natural input when and come from another program or from the literature. Elements may also be named by term label; - a list of natural-scale parameter vectors, as in
fit$covPar; - a data frame with columns
term,parameterandvalue, such asebv$vcParams.
Here we use the true matrices. The predictions are almost identical to those obtained with the pilot estimates, so estimating the variances on 20% of the data costs little accuracy:
ebvTrue <- mmes(value ~ trait + trait:herd,
                random = ~ vsm(usm(trait), ism(id), Gu=Ainv),
                rcov = ~ vsm(usm(trait), ism(record)),
                data=long, solveOnly=TRUE, covPar=list(G0, R0), verbose=FALSE)
## Adding 3000 additional Gu levels to the main-effect model matrix: A15001, A15002, A15003, A15004, A15005, A15006, A15007, A15008, A15009, A15010 ...## Engine selected: known-covariance PCG (solveOnly=TRUE)## y1 y2
## 0.9987345 0.9984394## y1 y2
## 0.4940664 0.4970278
ebvTrue$vcParams[, c("term", "parameter", "value")]## term parameter value
## 1 vsm(usm(trait), ism(id), Gu = Ainv) sigma2 0.3000000
## 2 vsm(usm(trait), ism(id), Gu = Ainv) usm(trait):chol[y2,y1] 0.7666667
## 3 vsm(usm(trait), ism(id), Gu = Ainv) usm(trait):chol_diag[y2] 1.0386958
## 4 vsm(usm(trait), ism(record)) sigma2 0.7000000
## 5 vsm(usm(trait), ism(record)) usm(trait):chol[y2,y1] 0.3428571
## 6 vsm(usm(trait), ism(record)) usm(trait):chol_diag[y2] 1.0808160For a single-trait evaluation, the known variances can also be
written directly in the formula and fixed, in which case
covPar is not needed:
single <- mmes(y1 ~ herd,
               random = ~ vsm(ism(id), Gu=Ainv, sigma2=0.30, fixedSigma2=TRUE),
               rcov = ~ vsm(ism(units), sigma2=0.70, fixedSigma2=TRUE),
               data=pheno, solveOnly=TRUE, verbose=FALSE)
## Adding 3000 additional Gu levels to the main-effect model matrix: A15001, A15002, A15003, A15004, A15005, A15006, A15007, A15008, A15009, A15010 ...## Engine selected: known-covariance PCG (solveOnly=TRUE)
cor(single$uList[[1]][candidates, 1], bv[candidates, "y1"])## [1] 0.4921655Practical notes
-
Scale. On a simulated pedigree with one million
animals (eight threads), the complete call took about 10 s for a single
trait and 40 s for three correlated traits (3 million equations), most
of it in R data preparation. Peak memory was 1.3 GB and 2.9 GB
respectively. The number of threads follows the usual OpenMP settings
(e.g.
OMP_NUM_THREADS). -
Convergence.
pcgTol(default1e-8) is the relative residual at which iterations stop, andpcgMaxIterslimits the number of iterations (0 selects an automatic limit). A warning is issued if the tolerance is not reached. Rankings usually stabilize well before the default tolerance. -
Matching the REML model. When
covParis a fitted object, the random and residual terms must be the same terms with the same labels; otherwise an error names the missing terms. Data, fixed effects and the levels of the relationship matrix may differ. -
Scope.
solveOnly=TRUEneeds a Gaussian model and a residual covariance that is block diagonal with blocks of at most 10000 records. Weights must be a diagonalW. It does not return prediction error variances, reliabilities, or a likelihood; use a regularmmes()fit withcomputeCifor those on problems of moderate size. -
Genomic information. Dense relationship precision
matrices (genomic or single-step) can be supplied as
Gu, but every iteration then costs as much as their number of nonzeros. For large genotyped populations, keep the inverse sparse, for example with the APY inverse fromAPY().