Fitting genotype by environment models in sommer
Giovanny Covarrubias-Pazaran
2026-10-06
Source:vignettes/sommer.gxe.Rmd
sommer.gxe.RmdThe sommer package was developed to provide R users with a flexible
univariate and multivariate linear mixed-model solver. The current
package provides two complementary REML formulations. The
mmes() function uses Henderson’s mixed model equations and
a sparse Average Information REML algorithm: the mixed-model coefficient
matrix is factorized with sparse LDLT methods, selected inverse elements
required by REML calculations can be obtained with Takahashi
sparse-inverse recursions, and the factorization is reused for
mixed-model solutions and variance-parameter derivatives. The
mmer() function uses the marginal-covariance MNR
formulation, in which REML calculations are organized around the
observation covariance matrix
and the REML projection matrix
.
The relative efficiency of the two formulations depends on model
dimensions, sparsity, and covariance structure rather than only on
whether
or
.
The core numerical algorithms are coded in C++ using Armadillo and
Eigen. The package allows users to specify flexible variance-covariance
structures for random and residual effects and to obtain quantities such
as REML variance-covariance estimates, BLUPs, BLUEs, residuals, fitted
values, and prediction error variance information.
The purpose of this vignette is to show how to fit different genotype by environment (GxE) models using the sommer package:
- Single environment model
- Multienvironment model: Main effect model
- Multienvironment model: Diagonal model (DG)
- Multienvironment model: Compund symmetry model (CS)
- Multienvironment model: Unstructured model (US)
- Multienvironment model: Random regression model (RR)
- Multienvironment model: Other covariance structures for GxE
- Multienvironment model: Finlay-Wilkinson regression
- Multienvironment model: Factor analytic (reduced rank) model (FA)
- Two stage analysis
When the breeder decides to run a trial and apply selection in a single environment (whether because the amount of seed is a limitation or there’s no availability for a location) the breeder takes the risk of selecting material for a target population of environments (TPEs) using an environment that is not representative of the larger TPE. Therefore, many breeding programs try to base their selection decision on multi-environment trial (MET) data. Models could be adjusted by adding additional information like spatial information, experimental design information, etc. In this tutorial we will focus mainly on the covariance structures for GxE and the incorporation of relationship matrices for the genotype effect.
1) Single environment model
A single-environment model is the one that is fitted when the breeding program can only afford one location, leaving out the possible information available from other environments. This will be used to further expand to GxE models.
## Loading required package: Matrix## Loading required package: MASS## Loading required package: crayon## Loading required package: enhancer
data(DT_example, package="enhancer")
DT <- DT_example
A <- A_example

Ai <- solve(A)
Ai <- as(as(as( Ai,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Ai, "inverse")=TRUE

ansSingle <- mmes(Yield~1,
              random= ~ vsm(ism(Name), Gu=Ai),
              rcov= ~ units,
              data=DT, verbose = FALSE)
## Solver selected: ldlt
summary(ansSingle)## ============================================================
## Multivariate Linear Mixed Model fit by REML
## ********************** sommer 4.4 **********************
## ============================================================
## logLik AIC BIC Method Converge
## Value -81.41893 164.8379 168.0582 AI TRUE
## ============================================================
## Variance-Covariance components:
## term parameter estimate StdError Zratio
## 1 vsm(ism(Name), Gu = Ai) sigma2 6.533 2.184 2.991
## 2 vsm(ism(units)) sigma2 13.865 1.629 8.513
## ============================================================
## Fixed effects:
## Estimate Std.Error t.value
## Intercept 11.74 NA NA
## ============================================================
## Use the '$' sign to access results and parametersIn this model, the random term is the germplasm effect (here called
Name). For the sake of example, a relationship structure
among the levels of Name is supplied through
Gu. In the code above Ai is the sparse
precision matrix corresponding to the relationship matrix
A, and attr(Ai, "inverse")=TRUE tells sommer
that the supplied matrix is already in precision form. More generally, a
non-diagonal relationship structure can be used to model covariance
among genotype levels.
2) MET: main effect model
A multi-environment model is the one that is fitted when the breeding program can afford more than one location. The main effect model assumes that GxE doesn’t exist and that the main genotype effect plus the fixed effect for environment is enough to predict the genotype effect in all locations of interest.
ansMain <- mmes(Yield~Env,
              random= ~ vsm(ism(Name), Gu=Ai),
              rcov= ~ units,
              data=DT, verbose = FALSE)
## Solver selected: ldlt
summary(ansMain)## ============================================================
## Multivariate Linear Mixed Model fit by REML
## ********************** sommer 4.4 **********************
## ============================================================
## logLik AIC BIC Method Converge
## Value -38.73391 83.46782 93.12888 AI TRUE
## ============================================================
## Variance-Covariance components:
## term parameter estimate StdError Zratio
## 1 vsm(ism(Name), Gu = Ai) sigma2 4.858 1.4994 3.240
## 2 vsm(ism(units)) sigma2 8.107 0.9575 8.467
## ============================================================
## Fixed effects:
## Estimate Std.Error t.value
## Intercept 16.385 NA NA
## EnvCA.2012 -5.688 NA NA
## EnvCA.2013 -6.218 NA NA
## ============================================================
## Use the '$' sign to access results and parameters3) MET: diagonal model (DG)
A multi-environment model is fitted when observations are available
from more than one environment. The diagonal GxE model allows the
genetic variance to differ among environments while constraining the
genetic covariance between different environments to zero. In the
current vsm() parameterization, dsm(Env) is a
normalized diagonal covariance factor: one product-level variance scale
is estimated by vsm() and the remaining diagonal parameters
are relative variance ratios. Thus the model has an environment-specific
genetic variance without estimating cross-environment genetic
covariances. The fixed environment effect and the environment-specific
genotype BLUP are then combined to predict performance in each
environment.
ansDG <- mmes(Yield~Env,
              random= ~ vsm(dsm(Env),ism(Name), Gu=Ai),
              rcov= ~ units,
              data=DT, verbose = FALSE)
## Solver selected: ldlt
summary(ansDG)## ============================================================
## Multivariate Linear Mixed Model fit by REML
## ********************** sommer 4.4 **********************
## ============================================================
## logLik AIC BIC Method Converge
## Value -27.18127 60.36254 70.02361 AI TRUE
## ============================================================
## Variance-Covariance components:
## term parameter estimate StdError Zratio
## 1 vsm(dsm(Env), ism(Name), Gu = Ai) variance[CA.2011] 17.472 6.0888 2.869
## 2 vsm(dsm(Env), ism(Name), Gu = Ai) variance[CA.2012] 5.339 1.7909 2.981
## 3 vsm(dsm(Env), ism(Name), Gu = Ai) variance[CA.2013] 7.886 2.5493 3.093
## 4 vsm(ism(units)) sigma2 4.381 0.6514 6.724
## ============================================================
## Fixed effects:
## Estimate Std.Error t.value
## Intercept 16.621 NA NA
## EnvCA.2012 -5.958 NA NA
## EnvCA.2013 -6.662 NA NA
## ============================================================
## Use the '$' sign to access results and parameters4) MET: compund symmetry model (CS)
A multi-environment model is fitted when observations are available from more than one environment. In the code below, compound-symmetry-like GxE behavior is represented by two independent random terms: a genotype main effect shared across environments and an environment-by-genotype deviation. Their covariance contribution is the sum of the two random-effect covariance matrices. Under the identity structures used here this implies a common covariance between observations on the same genotype in different environments, while the GxE deviation adds environment-specific variance. The fixed environment effect, genotype main-effect BLUP, and genotype-by-environment BLUP together describe performance in each environment.
E <- diag(length(unique(DT$Env)));rownames(E) <- colnames(E) <- unique(DT$Env)
Ei <- solve(E)
Ai <- solve(A)
EAi <- kronecker(Ei,Ai, make.dimnames = TRUE)
Ei <- as(as(as( Ei,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
Ai <- as(as(as( Ai,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
EAi <- as(as(as( EAi,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Ai, "inverse")=TRUE
attr(EAi, "inverse")=TRUE
ansCS <- mmes(Yield~Env,
              random= ~ vsm(ism(Name), Gu=Ai) + vsm(ism(Env:Name), Gu=EAi),
              rcov= ~ units,
              data=DT, verbose = FALSE)
## Adding 29 additional Gu levels to the main-effect model matrix: CA.2013:CO05061-2P, CA.2013:AC01151-5W, CA.2013:MSS165-2Y, CA.2013:NY148, CA.2013:W8539-2Y, CA.2013:W8615-5, CA.2013:MSR148-4, CA.2013:CO00270-7W, CA.2011:Manistee(MSL292-A), CA.2011:AC05153-1W ...## Solver selected: ldlt
summary(ansCS)## ============================================================
## Multivariate Linear Mixed Model fit by REML
## ********************** sommer 4.4 **********************
## ============================================================
## logLik AIC BIC Method Converge
## Value -26.28507 58.57015 68.23121 AI TRUE
## ============================================================
## Variance-Covariance components:
## term parameter estimate StdError Zratio
## 1 vsm(ism(Name), Gu = Ai) sigma2 3.684 1.6274 2.263
## 2 vsm(ism(Env:Name), Gu = EAi) sigma2 5.171 1.4764 3.502
## 3 vsm(ism(units)) sigma2 4.367 0.6487 6.732
## ============================================================
## Fixed effects:
## Estimate Std.Error t.value
## Intercept 16.496 NA NA
## EnvCA.2012 -5.777 NA NA
## EnvCA.2013 -6.380 NA NA
## ============================================================
## Use the '$' sign to access results and parameters5) MET: unstructured model (US)
The unstructured GxE model allows a distinct genetic variance for
each environment and a distinct genetic covariance for every pair of
environments. In the current vsm() architecture,
usm(Env) is represented by a normalized Cholesky covariance
factor and vsm() supplies the single product-level variance
scale. This parameterization guarantees positive definiteness for
admissible working parameters while retaining the flexibility of an
unstructured covariance matrix. Because the number of covariance-shape
parameters grows rapidly with the number of environments, these models
can still be statistically weakly identified or computationally
demanding. The fixed environment effect and the correlated
environment-specific genotype BLUPs are used to predict performance in
each environment.
ansUS <- mmes(Yield~Env,
              random= ~ vsm(usm(Env),ism(Name), Gu=Ai),
              rcov= ~ units,
              data=DT, verbose = FALSE)
## Solver selected: ldlt
summary(ansUS)## ============================================================
## Multivariate Linear Mixed Model fit by REML
## ********************** sommer 4.4 **********************
## ============================================================
## logLik AIC BIC Method Converge
## Value -20.34919 46.69838 56.35945 AI TRUE
## ============================================================
## Variance-Covariance components:
## term parameter estimate
## 1 vsm(usm(Env), ism(Name), Gu = Ai) variance[CA.2011] 15.9857
## 2 vsm(usm(Env), ism(Name), Gu = Ai) covariance[CA.2012,CA.2011] 6.1692
## 3 vsm(usm(Env), ism(Name), Gu = Ai) covariance[CA.2013,CA.2011] 6.3638
## 4 vsm(usm(Env), ism(Name), Gu = Ai) variance[CA.2012] 5.2744
## 5 vsm(usm(Env), ism(Name), Gu = Ai) covariance[CA.2013,CA.2012] 0.3746
## 6 vsm(usm(Env), ism(Name), Gu = Ai) variance[CA.2013] 7.6896
## 7 vsm(ism(units)) sigma2 4.3859
## StdError Zratio
## 1 5.2288 3.0573
## 2 2.4710 2.4966
## 3 2.8812 2.2087
## 4 1.7708 2.9786
## 5 1.5598 0.2402
## 6 2.4698 3.1134
## 7 0.6525 6.7216
## ============================================================
## Fixed effects:
## Estimate Std.Error t.value
## Intercept 16.341 NA NA
## EnvCA.2012 -5.696 NA NA
## EnvCA.2013 -6.286 NA NA
## ============================================================
## Use the '$' sign to access results and parameters6) MET: random regression model
A random regression model represents environmental response with a continuous covariate or a set of basis functions, here Legendre polynomials of the numeric environment index. Genotype-specific coefficients on these basis functions describe reaction norms across environments. The covariance structure assigned to the basis coefficients determines how the random intercept, slopes, and higher-order coefficients vary and covary. Consequently, the number of covariance parameters depends both on the polynomial order and on the covariance structure placed on the basis coefficients.
library(orthopolynom)
DT$EnvN <- as.numeric(as.factor(DT$Env))

ansRR <- mmes(Yield~Env,
              random= ~ vsm(dsm(leg(EnvN,1)),ism(Name)),
              rcov= ~ units,
              data=DT, verbose = FALSE)
## Solver selected: ldlt
summary(ansRR)## ============================================================
## Multivariate Linear Mixed Model fit by REML
## ********************** sommer 4.4 **********************
## ============================================================
## logLik AIC BIC Method Converge
## Value -33.84286 73.68572 83.34679 AI TRUE
## ============================================================
## Variance-Covariance components:
## term parameter estimate StdError Zratio
## 1 vsm(dsm(leg(EnvN, 1)), ism(Name)) variance[leg0] 10.389 3.0820 3.371
## 2 vsm(dsm(leg(EnvN, 1)), ism(Name)) variance[leg1] 2.081 0.9939 2.094
## 3 vsm(ism(units)) sigma2 6.296 0.8548 7.365
## ============================================================
## Fixed effects:
## Estimate Std.Error t.value
## Intercept 16.541 NA NA
## EnvCA.2012 -5.832 NA NA
## EnvCA.2013 -6.472 NA NA
## ============================================================
## Use the '$' sign to access results and parametersIn addition, an unstructured, diagonal or other variance-covariance structure can be put on top of the polynomial model:
library(orthopolynom)
DT$EnvN <- as.numeric(as.factor(DT$Env))

ansRR <- mmes(Yield~Env,
              random= ~ vsm(usm(leg(EnvN,1)),ism(Name)),
              rcov= ~ units,
              data=DT, verbose = FALSE)
## Solver selected: ldlt
summary(ansRR)## ============================================================
## Multivariate Linear Mixed Model fit by REML
## ********************** sommer 4.4 **********************
## ============================================================
## logLik AIC BIC Method Converge
## Value -31.70935 69.41871 79.07978 AI TRUE
## ============================================================
## Variance-Covariance components:
## term parameter estimate StdError
## 1 vsm(usm(leg(EnvN, 1)), ism(Name)) variance[leg0] 10.788 3.2124
## 2 vsm(usm(leg(EnvN, 1)), ism(Name)) covariance[leg1,leg0] -2.428 1.3610
## 3 vsm(usm(leg(EnvN, 1)), ism(Name)) variance[leg1] 2.288 1.0754
## 4 vsm(ism(units)) sigma2 6.259 0.8533
## Zratio
## 1 3.358
## 2 -1.784
## 3 2.128
## 4 7.335
## ============================================================
## Fixed effects:
## Estimate Std.Error t.value
## Intercept 16.501 NA NA
## EnvCA.2012 -5.791 NA NA
## EnvCA.2013 -6.476 NA NA
## ============================================================
## Use the '$' sign to access results and parameters7) Other GxE covariance structures
Many structured covariance models can be used for GxE when their
assumptions are appropriate for the ordering or relationship among
environments. In the example below csm(Env) specifies a
homogeneous correlation structure for the environment covariance factor.
Other available structures, such as autoregressive models for
meaningfully ordered environments, can be substituted within the same
vsm() product architecture.
ansAR1 <- mmes(Yield~Env,
              random= ~ vsm(csm(Env),ism(Name)),
              rcov= ~ units,
              data=DT, verbose = FALSE)
## Solver selected: ldlt
summary(ansAR1)## ============================================================
## Multivariate Linear Mixed Model fit by REML
## ********************** sommer 4.4 **********************
## ============================================================
## logLik AIC BIC Method Converge
## Value -26.2851 58.5702 68.23127 AI TRUE
## ============================================================
## Variance-Covariance components:
## term parameter estimate StdError Zratio
## 1 vsm(csm(Env), ism(Name)) variance 8.8448 1.7868 4.950
## 2 vsm(csm(Env), ism(Name)) rho 0.4156 0.1463 2.841
## 3 vsm(ism(units)) sigma2 4.3700 0.6494 6.729
## ============================================================
## Fixed effects:
## Estimate Std.Error t.value
## Intercept 16.496 NA NA
## EnvCA.2012 -5.777 NA NA
## EnvCA.2013 -6.381 NA NA
## ============================================================
## Use the '$' sign to access results and parameters8) Finlay-Wilkinson regression
data(DT_h2, package="enhancer")
DT <- DT_h2

## build the environmental index
ei <- aggregate(y~Env, data=DT,FUN=mean)
colnames(ei)[2] <- "envIndex"
ei$envIndex <- ei$envIndex - mean(ei$envIndex,na.rm=TRUE) # center the envIndex to have clean VCs
ei <- ei[with(ei, order(envIndex)), ]

## add the environmental index to the original dataset
DT2 <- merge(DT,ei, by="Env")

# numeric by factor variables like envIndex:Name can't be used in the random part like this
# they need to come with the vsm() structure
DT2 <- DT2[with(DT2, order(Name)), ]
mix2 <- mmes(y~ envIndex,
             random=~ Name + vsm(ism(envIndex),ism(Name)), data=DT2,
             rcov=~vsm(dsm(Name),ism(units)),
             nIters = 50, verbose = FALSE
)
## Solver selected: ldlt
# summary(mix2)$varcomp

b=mix2$uList$`vsm(ism(envIndex), ism(Name` # adaptability (b) or genotype slopes
mu=mix2$uList$`vsm(ism(Name`# general adaptation (mu) or main effect
e=sqrt(summary(mix2)$varcomp[-c(1:2),"estimate"]) # error variance for each individual

## general adaptation (main effect) vs adaptability (response to better environments)
plot(mu[,1]~b[,1], ylab="general adaptation", xlab="adaptability")
text(y=mu[,1],x=b[,1], labels = rownames(mu), cex=0.5, pos = 1)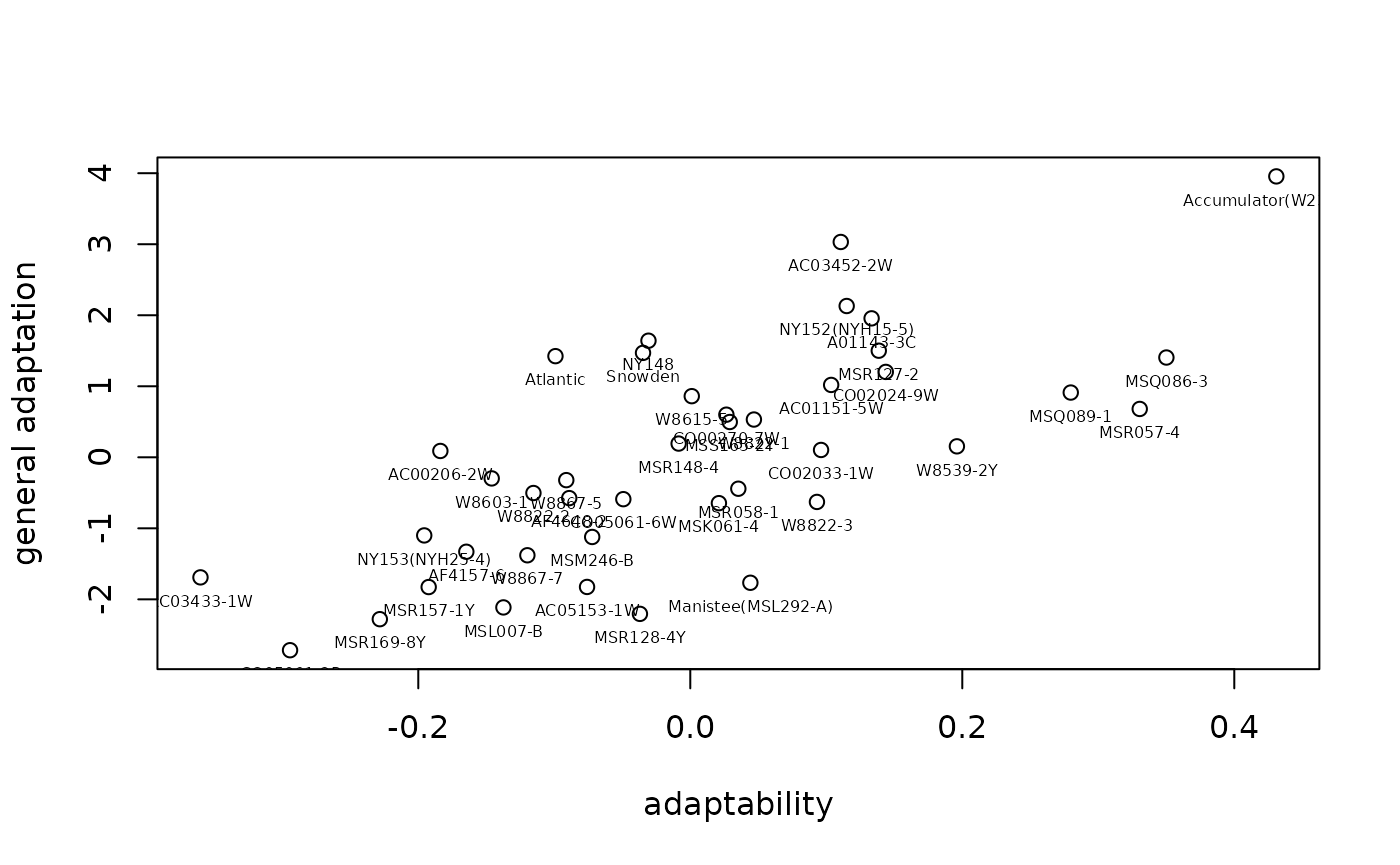
## prediction across environments
Dt <- mix2$Dtable
Dt[1,"average"]=TRUE
Dt[2,"include"]=TRUE
Dt[3,"include"]=TRUE

mix2 <- postPEV(mix2, mode=2)
pp <- predict(mix2,Dtable = Dt, D="Name")
preds <- pp$pvals
# preds[with(preds, order(-predicted.value)), ]
## performance vs stability (deviation from regression line)
plot(preds[,2]~e, ylab="performance", xlab="stability")
text(y=preds[,2],x=e, labels = rownames(mu), cex=0.5, pos = 1)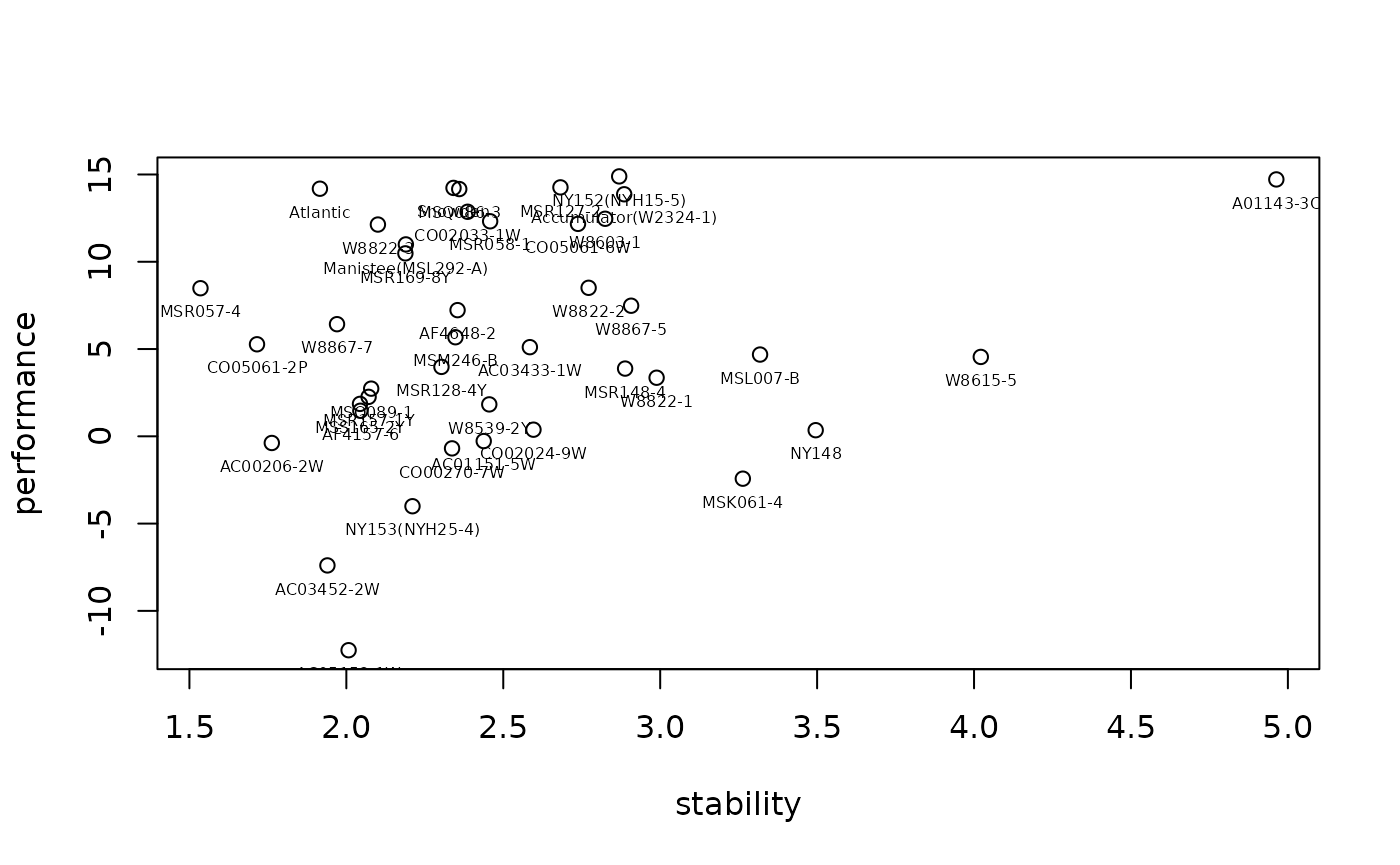
9) Factor analytic and reduced rank models
When the number of environments is large, a fully unstructured
genetic covariance requires
covariance parameters for
environments and can become weakly identified relative to the available
information. Reduced-rank and factor-analytic representations provide a
more parsimonious alternative. In the first implementation below, we
show the use of the factor analytic structure fam() where
loadings and specific variances are estimated through REML and produce
predictions.
##          Name     Env Loc Year     Block  y
## 67   MSL007-B CA.2011  CA 2011 CA.2011.2  5
## 105  MSL007-B CA.2011  CA 2011 CA.2011.1  6
## 308  MSK061-4 CA.2011  CA 2011 CA.2011.2  9
## 393  MSK061-4 CA.2011  CA 2011 CA.2011.1 10
## 469 MSR169-8Y CA.2011  CA 2011 CA.2011.1 11
## 471     NY148 CA.2011  CA 2011 CA.2011.1 11
indNames <- na.omit(unique(DT$Name))
A <- diag(length(indNames))
rownames(A) <- colnames(A) <- indNames

# factor analytic model with 2 factors
ansFA2 <- mmes(y~Env,
               random=~vsm( fam(Env, 2) , ism(Name)) ,
               rcov=~units,
               nIters = 100, verbose = FALSE,
               data=DT)
## Solver selected: ldlt
Dt <- ansFA2$Dtable; Dt## type term include average levels
## 1 fixed 1 FALSE FALSE NULL
## 2 fixed Env FALSE FALSE NULL
## 3 random vsm(fam(Env, 2), ism(Name)) FALSE FALSE NULL
Dt[1:2,"average"]=TRUE
Dt[3,c("average","include")]=TRUE

ppfa <- predict(ansFA2, D="Env:Name", Dtable = Dt)
head(ppfa$pvals)
## Env:Name predicted.value std.error pev
## CA.2011:A01143-3C CA.2011:A01143-3C 17.72739 1.3831466 1.91309448
## CA.2012:A01143-3C CA.2012:A01143-3C 12.02340 1.1429048 1.30623143
## CA.2013:A01143-3C CA.2013:A01143-3C 19.44638 1.2267732 1.50497256
## FL.2011:A01143-3C FL.2011:A01143-3C 11.69483 0.5023346 0.25234003
## FL.2012:A01143-3C FL.2012:A01143-3C 11.70725 0.2991085 0.08946588
## FL.2013:A01143-3C FL.2013:A01143-3C 11.78597 0.2808610 0.07888292
## var.u
## CA.2011:A01143-3C 13.5928310
## CA.2012:A01143-3C 3.9902740
## CA.2013:A01143-3C 6.2851780
## FL.2011:A01143-3C 1.4129515
## FL.2012:A01143-3C 0.2908999
## FL.2013:A01143-3C 0.0000000If needed, loadings and factor scores can be extracted with the
loadings_mmes() and scores_mmes() functions.
The second implementation below uses the reduced rank implementation
available with the rrm() function to estimate loadings
through REML and we use a diagonal term (dsm) to fit the environment
specific variances.
# reduced rank model with 2 factors
ansRR2 <- mmes(y~Env, henderson=TRUE,
              random=~vsm( rrm(Env, 2) , ism(Name)) + # rr
                vsm(dsm(Env), ism(Name)), # diag
              rcov=~units,
              nIters = 100, verbose = FALSE,
              data=DT)
## Solver selected: ldlt
Dt <- ansRR2$Dtable; Dt## type term include average levels
## 1 fixed 1 FALSE FALSE NULL
## 2 fixed Env FALSE FALSE NULL
## 3 random vsm(rrm(Env, 2), ism(Name)) FALSE FALSE NULL
## 4 random vsm(dsm(Env), ism(Name)) FALSE FALSE NULL
Dt[1:2,"average"]=TRUE
Dt[3:4,c("average","include")]=TRUE

pprr <- predict(ansRR2, D="Env:Name", Dtable = Dt)
head(pprr$pvals)
## Env:Name predicted.value std.error pev
## CA.2011:A01143-3C CA.2011:A01143-3C 17.72535 1.3837243 1.91469298
## CA.2012:A01143-3C CA.2012:A01143-3C 12.02355 1.1430456 1.30655332
## CA.2013:A01143-3C CA.2013:A01143-3C 19.44686 1.2266952 1.50478120
## FL.2011:A01143-3C FL.2011:A01143-3C 11.69112 0.4982976 0.24830054
## FL.2012:A01143-3C FL.2012:A01143-3C 11.70628 0.3095111 0.09579710
## FL.2013:A01143-3C FL.2013:A01143-3C 11.78601 0.2805777 0.07872383
## var.u
## CA.2011:A01143-3C 13.5699632
## CA.2012:A01143-3C 3.9843518
## CA.2013:A01143-3C 6.2721962
## FL.2011:A01143-3C 1.4156538
## FL.2012:A01143-3C 0.2910462
## FL.2013:A01143-3C 0.0000000
# compare
plot(ppfa$pvals[,"predicted.value"],pprr$pvals[,"predicted.value"])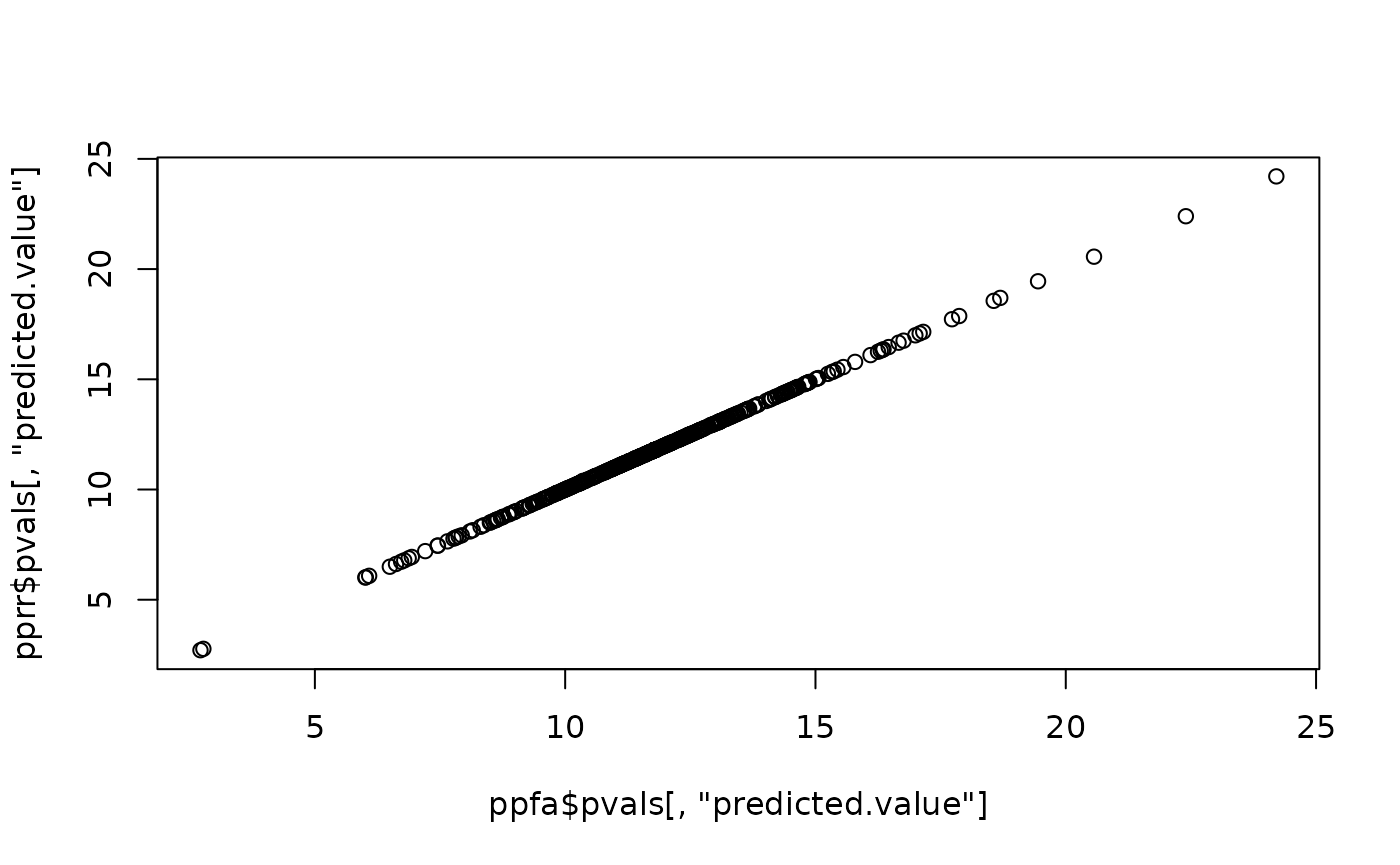
Last but not least, it is possible to avoid the estimation of loadings by defining fixed loadings as covariates of a random regression coming from a diagonal model that uses the GxE predictions to derive Sigma and the fixed loadings.
# fit diagonal model first to produce H matrix
ansDG <- mmes(y~Env, henderson=TRUE,
              random=~ vsm(dsm(Env), ism(Name)),
              rcov=~units, nIters = 100,
              data=DT, verbose = FALSE)
## Solver selected: ldlt
H0 <- ansDG$uList$`vsm(dsm(Env), ism(Name))` # GxE table

# # reduced rank model
# ansFA <- mmes(y~Env, henderson=TRUE,
#               random=~vsm( usm(rrmat(Env, H = H0, nPC = 2)) , ism(Name)) + # rr
#                 vsm(dsm(Env), ism(Name)), # diag
#               rcov=~units,
#               # we recommend giving more iterations to these models
#               nIters = 100, verbose = FALSE,
#               # we recommend giving more EM iterations at the beggining
#               data=DT)
#
# vcFA <- ansFA$theta[[1]]
# vcDG <- ansFA$theta[[2]]
#
# loadings=with(DT, rrmat(Env, nPC = 2, H = H0, returnGamma = TRUE) )$Gamma
# scores <- ansFA$uList[[1]]
#
# vcUS <- loadings %*% vcFA %*% t(loadings)
# G <- vcUS + vcDG
# # colfunc <- colorRampPalette(c("steelblue4","springgreen","yellow"))
# # hv <- heatmap(cov2cor(G), col = colfunc(100), symm = TRUE)
#
# uFA <- scores %*% t(loadings)
# uDG <- ansFA$uList[[2]]
# u <- uFA + uDG
#
# plot(ppfa$pvals[,"predicted.value"],as.vector(t(u)))
# plot(as.vector(t(u)),pprr$pvals[,"predicted.value"])
10) Two stage analysis
In two-stage analyses, a first-stage mixed model is commonly fitted
to account for experimental-design and field variation while treating
the entry effects of interest as fixed, producing adjusted entry means
(BLUEs or EMMs). Their estimation-error covariance should be carried
into the second stage rather than treating the adjusted means as
independent observations with equal precision. In the example below,
computeCi = 2 requests the complete coefficient-matrix
inverse after fitting each first-stage model; the fixed-effect block is
used to construct the corresponding precision contribution for the
second-stage weight matrix W. The second-stage mixed model
then analyzes the adjusted means while retaining this first-stage
precision information.
##########
## stage 1
## use mmes for dense field trials
##########
data(DT_h2, package="enhancer")
DT <- DT_h2
head(DT)
## Name Env Loc Year Block y
## 1 W8822-3 FL.2012 FL 2012 FL.2012.1 2
## 2 W8867-7 FL.2012 FL 2012 FL.2012.2 2
## 3 MSL007-B MO.2011 MO 2011 MO.2011.1 3
## 4 CO00270-7W FL.2012 FL 2012 FL.2012.2 3
## 5 Manistee(MSL292-A) FL.2013 FL 2013 FL.2013.2 3
## 6 MSM246-B FL.2012 FL 2012 FL.2012.2 3
envs <- unique(DT$Env)
BLUEL <- list()
XtXL <- list()
for(i in 1:length(envs)){
  ans1 <- mmes(y~Name-1,
               random=~Block,
               verbose=FALSE,
               computeCi = 2,
               data=droplevels(DT[which(DT$Env == envs[i]),])
  )
  ans1$Beta$Env <- envs[i]

  BLUEL[[i]] <- data.frame( Effect=factor(rownames(ans1$b)),
                            Estimate=ans1$b[,1],
                            Env=factor(envs[i]))
  # to be comparable to 1/(se^2) = 1/PEV = 1/Ci = 1/[(X'X)inv]
  XtXL[[i]] <- solve(ans1$Ci[1:nrow(ans1$b),1:nrow(ans1$b)])
}
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
## Solver selected: cholmod
DT2 <- do.call(rbind, BLUEL)
OM <- Reduce(adiag1,lapply(XtXL,as.matrix))

##########
## stage 2
## use mmes for sparse equation
##########
m <- matrix(1/var(DT2$Estimate, na.rm = TRUE))

ans2 <- mmes(Estimate~Env, henderson=TRUE,
             random=~ Effect + Env:Effect,
             rcov = ~ vsm(
               ism(units),
               sigma2 = 1,
               fixedSigma2 = TRUE
             ),
             W=OM,
             verbose=FALSE,
             data=DT2
)
## Solver selected: ldlt## Using the weights matrix
summary(ans2)$varcomp## term parameter estimate StdError
## 1 vsm(ism(Effect)) sigma2 2.076894 0.5759343
## 2 vsm(ism(Env:Effect)) sigma2 3.337166 0.3708767
## 3 vsm(ism(units), sigma2 = 1, fixedSigma2 = TRUE) sigma2 1.000000 0.0000000
## Zratio
## 1 3.606129
## 2 8.998047
## 3 NALiterature
Covarrubias-Pazaran G. 2016. Genome assisted prediction of quantitative traits using the R package sommer. PLoS ONE 11(6):1-15.
Covarrubias-Pazaran G. 2018. Software update: Moving the R package sommer to multivariate mixed models for genome-assisted prediction. doi: https://doi.org/10.1101/354639
Bernardo Rex. 2010. Breeding for quantitative traits in plants. Second edition. Stemma Press. 390 pp.
Gilmour et al. 1995. Average Information REML: An efficient algorithm for variance parameter estimation in linear mixed models. Biometrics 51(4):1440-1450.
Henderson C.R. 1975. Best Linear Unbiased Estimation and Prediction under a Selection Model. Biometrics vol. 31(2):423-447.
Kang et al. 2008. Efficient control of population structure in model organism association mapping. Genetics 178:1709-1723.
Lee, D.-J., Durban, M., and Eilers, P.H.C. (2013). Efficient two-dimensional smoothing with P-spline ANOVA mixed models and nested bases. Computational Statistics and Data Analysis, 61, 22 - 37.
Lee et al. 2015. MTG2: An efficient algorithm for multivariate linear mixed model analysis based on genomic information. Cold Spring Harbor. doi: http://dx.doi.org/10.1101/027201.
Maier et al. 2015. Joint analysis of psychiatric disorders increases accuracy of risk prediction for schizophrenia, bipolar disorder, and major depressive disorder. Am J Hum Genet; 96(2):283-294.
Rodriguez-Alvarez, Maria Xose, et al. Correcting for spatial heterogeneity in plant breeding experiments with P-splines. Spatial Statistics 23 (2018): 52-71.
Searle. 1993. Applying the EM algorithm to calculating ML and REML estimates of variance components. Paper invited for the 1993 American Statistical Association Meeting, San Francisco.
Yu et al. 2006. A unified mixed-model method for association mapping that accounts for multiple levels of relatedness. Genetics 38:203-208.
Tunnicliffe W. 1989. On the use of marginal likelihood in time series model estimation. JRSS 51(1):15-27.