Quantitative genetics using the sommer package
Giovanny Covarrubias-Pazaran
2026-10-06
Source:vignettes/sommer.qg.Rmd
sommer.qg.RmdThe sommer package was developed to provide R users with flexible
univariate and multivariate linear mixed-model tools for genetic and
non-genetic analyses in diploid and polyploid organisms. The package can
estimate variance-covariance parameters while allowing structured
covariance models for random and residual effects, heterogeneous
variances, and extraction of quantities such as BLUPs, BLUEs, residuals,
fitted values, and prediction-error information. The current
mmes() implementation uses Henderson’s mixed model
equations with a sparse Average Information REML algorithm. Its
numerical core uses sparse LDLT factorization, reuses the factorization
for mixed-model solutions and variance-parameter differentiation, and
can compute selected inverse elements with Takahashi sparse-inverse
recursions when required by the REML calculations. Covariance factors
supplied through vsm() are handled through a generic
descriptor architecture and can be combined in arbitrary Kronecker
products. The package also retains the complementary marginal-covariance
MNR formulation through mmer(). The relative computational
advantage of the two formulations depends on model dimensions, sparsity,
and covariance structure rather than on a single p versus
n rule.
The package supports a broad range of quantitative-genetic mixed
models, including genomic prediction, hybrid prediction, GWAS-related
analyses, multi-environment and multivariate models, and general
mixed-model applications. It provides functions to construct additive
(A.mat), dominance (D.mat), and epistatic
(E.mat) relationship matrices, which can be incorporated as
covariance or precision structures as appropriate for the solver being
used. The package also provides flexibility for genetic models such as
full and half diallel designs.
The vignettes aim to provide several examples in how to use the sommer package under different scenarios. We will spend the rest of the space providing examples for:
SECTION 1: Introduction
- Background in linear algebra
SECTION 2: Topics in quantitative genetics
- Heritability () calculation
- Specifying heterogeneous variances in mixed models
- Using the
vpredict()calculator - Half and full diallel designs (using the overlay)
- Genomic selection (predicting mendelian sampling)
- GBLUP
- rrBLUP
- Indirect genetic effects
- Single cross prediction (hybrid prediction)
- Multivariate genetic models and genetic correlations
- Bivariate model with repeated records
SECTION 3: Special topics in quantitative genetics
- Partitioned model
- UDU’ decomposition
- Mating designs
- GWAS by GBLUP
- Reduced models
SECTION 1: Introduction
Backgrounds in linear algebra
The package provides two complementary REML computational
formulations. The current mmes() function solves
Henderson’s mixed model equations and estimates covariance parameters
with a sparse Average Information REML algorithm. The mixed-model
coefficient matrix is factorized using sparse LDLT methods, and the same
factorization is reused to solve the equations and to obtain the exact
forward derivatives needed by the AI calculations. The
mmer() function provides the marginal-covariance MNR
formulation, in which computations are organized around the observation
covariance matrix and the REML projection matrix. Since version 2.0,
sommer can handle multivariate models. Following the usual multivariate
mixed-model notation, the multivariate (and, by extension, univariate)
model has the form:
…
where
is a vector of trait phenotypes,
is a vector of fixed effects,
is a vector of random effects for individuals and
are residuals for trait i (i = 1, …, t). The random effects
(
…
and
)
are assumed to be normally distributed with mean zero. X and Z are
incidence matrices for fixed and random effects respectively. The
distributions of the multivariate response and the phenotypic variance
covariance (V) are:
Y ~ MVN(, V)
where
denotes a relationship or covariance structure associated with a random
effect. More generally, sommer permits several random terms and
structured residual covariance, so the marginal covariance can be
written as
.
The quantities
and
denote trait-specific random-effect and residual variances, while the
corresponding off-diagonal terms denote covariances between traits. In
the current vsm() architecture, each covariance term can
itself be constructed from one or more normalized covariance factors and
a single product-level variance scale. REML estimation is based on the
restricted log likelihood; ignoring constants, the usual marginal form
is:
where
,
and
denotes a determinant. This expression describes the marginal REML
criterion. In mmes(), the same REML objective is evaluated
through identities associated with Henderson’s mixed model equations
rather than by repeatedly forming and directly inverting the full
observation covariance matrix. Variance parameters are updated using an
Average Information step of the general form:
Here
denotes the working covariance-parameter vector,
is the REML score, and
is the Average Information matrix. For structured covariance factors,
mmes() differentiates the factorized mixed-model solve
analytically with respect to the covariance parameters and assembles the
AI system from those derivatives. Parameters are represented in working
coordinates chosen to respect covariance constraints, and the proposed
update is protected by trust scaling and a global exact-likelihood
backtracking procedure. For nonlinear covariance parameterizations the
AI matrix uses first covariance derivatives, rather than adding second
derivatives of the covariance model that belong to an observed-Hessian
formulation. The vpredict() function can subsequently use
estimated variance-covariance information and the delta method to obtain
standard errors for functions such as heritabilities and genetic
correlations.
Please refer to the canonical papers listed in the Literature section to check how the algorithms work. We have tested widely the methods to make sure they provide the same solution when the likelihood behaves well, but for complex problems they might lead to slightly different answers. If you have any concern please contact me at cova_ruber@live.com.mx.
In the following section we will go in detail over several examples on how to use mixed models in univariate and multivariate case and their use in quantitative genetics.
SECTION 2: Topics in quantitative genetics
1) Marker and non-marker based heritability calculation
Heritability is one of the most popular parameters among the breeding and genetics communities because of the insight it provides in the inheritance of the trait and potential selection response. Heritability is usually estimated as narrow sense (; only additive variance in the numerator ), and broad sense (; all genetic variance in the numerator ).
In a classical breeding experiment without molecular markers, mating
and experimental designs can be used to partition additive
()
and non-additive components such as dominance
()
and epistasis, together with environmental variation. Designs such as
generation analysis and the North Carolina designs can identify additive
and dominance components under their corresponding assumptions. When
such information is unavailable, replicated genotype effects can still
be used to estimate total genetic variance and broad-sense heritability.
The first example illustrates this latter case without a genomic
relationship matrix. Because the current mmes() solver is
based on sparse mixed model equations, models composed of sparse
incidence matrices and simple covariance structures are now directly
within its intended computational setting; the older warning about a
dense direct-inversion implementation no longer applies.
The following dataset has 41 potato lines evaluated in 5 locations across 3 years in an RCBD design. We show how to fit the model and extract the variance components to calculate the .
## Loading required package: Matrix## Loading required package: MASS## Loading required package: crayon## Loading required package: enhancer
data(DT_example, package="enhancer")
DT <- DT_example
A <- A_example

ans1 <- mmes(Yield~1,
             random= ~ Name + Env + Env:Name + Env:Block,
             rcov= ~ units,
             data=DT, verbose = FALSE)
## Solver selected: cholmod
summary(ans1)$varcomp## term parameter estimate StdError Zratio
## 1 vsm(ism(Name)) sigma2 3.718617e+00 1.6328695 2.2773512022
## 2 vsm(ism(Env)) sigma2 1.200805e+01 12.3103155 0.9754461074
## 3 vsm(ism(Env:Name)) sigma2 5.151848e+00 1.4732265 3.4969831378
## 4 vsm(ism(Env:Block)) sigma2 8.311396e-05 0.1703641 0.0004878607
## 5 vsm(ism(units)) sigma2 4.366648e+00 0.6532931 6.6840569882## [1] 3
vpredict(ans1, h2 ~ V1 / ( V1 + (V3/n.env) + (V5/(2*n.env)) ) )## Estimate SE
## h2 0.6033117 0.1160515That is an estimate of broad-sense heritability.
Recently with markers becoming cheaper, thousand of markers can be run in the breeding materials. When markers are available, a special design is not neccesary to dissect the additive genetic variance. The availability of the additive, dominance and epistatic relationship matrices allow us to estimate , and , although given that A, D and E are not orthogonal the interpretation of models that fit more than the A matrix at the same time becomes cumbersome.
Assume you have a population (even unreplicated) in the field but in addition we have genetic markers. Now we can fit the model and estimate the genomic heritability that explains a portion of the additive genetic variance (with high marker density = )
data(DT_cpdata, package="enhancer")
DT <- DT_cpdata
GT <- GT_cpdata
MP <- MP_cpdata
DT$idd <-DT$id; DT$ide <-DT$id
### look at the data
A <- A.mat(GT) # additive relationship matrix
D <- D.mat(GT) # dominance relationship matrix
E <- E.mat(GT) # epistatic relationship matrix

Ai <- solve(A + diag(1e-5, nrow(A), nrow(A)))
Ai[lower.tri(Ai)] <- t(Ai)[lower.tri(Ai)] # fill the lower triangular
Ai <- as(as(as( Ai,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Ai, "inverse")=TRUE

Di <- solve(D+ diag(1e-5, nrow(A), nrow(A)))
Di <- as(as(as( Di,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Di, "inverse")=TRUE


# ans.ADE <- mmes(Yield~1,
#                  random=~vsm(ism(id),Gu=Ai) + vsm(ism(idd),Gu=Di),
#                  rcov=~units, nIters=10,
#                  data=DT,verbose = FALSE)
# (summary(ans.ADE)$varcomp)
# vpredict(ans.ADE, h2 ~ (V1) / ( V1+V3) ) # narrow sense
# vpredict(ans.ADE, h2 ~ (V1+V2) / ( V1+V2+V3) ) # broad-sense
This example illustrates how marker-derived additive and dominance
relationship structures can be associated with random effects and used
to estimate additive and dominance variance components, from which
narrow- and broad-sense heritability functions can be formed. In the
current Henderson-based mmes() interface,
vsm() defines the covariance structure of a random term.
When a matrix supplied through Gu is already a precision
matrix, as Ai and Di are in the code above, it
is converted to sparse form and marked with
attr(..., "inverse")=TRUE. Thus the solver can use the
supplied precision directly rather than inverting it internally. This
replaces the older henderson=FALSE direct-inversion
distinction.
2) Specifying heterogeneous variances in univariate models
Very often in multi-environment trials, the assumption that genetic variance is the same across locations may be too naive. Because of that, specifying a general genetic component and a location-specific genetic variance is the way to go.
We estimate variance components for and specifying the variance structure.
data(DT_cornhybrids, package="enhancer")
DT <- DT_cornhybrids
DTi <- DTi_cornhybrids
GT <- GT_cornhybrids
### fit the model
modFD <- mmes(Yield~1,
              random=~ vsm(atm(Location,c("3","4")),ism(GCA2)),
              rcov= ~ vsm(dsm(Location),ism(units)),
              data=DT, verbose = FALSE)
## Solver selected: ldlt
summary(modFD)## ============================================================
## Multivariate Linear Mixed Model fit by REML
## ********************** sommer 4.4 **********************
## ============================================================
## logLik AIC BIC Method Converge
## Value -167.6796 337.3592 341.3506 AI TRUE
## ============================================================
## Variance-Covariance components:
## term parameter estimate StdError
## 1 vsm(atm(Location, c("3", "4")), ism(GCA2)) variance[3] 62.39 56.53
## 2 vsm(atm(Location, c("3", "4")), ism(GCA2)) variance[4] 98.02 82.46
## 3 vsm(dsm(Location), ism(units)) variance[1] 216.74 30.71
## 4 vsm(dsm(Location), ism(units)) variance[2] 216.83 30.73
## 5 vsm(dsm(Location), ism(units)) variance[3] 493.12 77.91
## 6 vsm(dsm(Location), ism(units)) variance[4] 712.03 112.13
## Zratio
## 1 1.104
## 2 1.189
## 3 7.057
## 4 7.056
## 5 6.329
## 6 6.350
## ============================================================
## Fixed effects:
## Estimate Std.Error t.value
## Intercept 138.1 NA NA
## ============================================================
## Use the '$' sign to access results and parametersIn the previous example atm() is used as a
covariance-shaping factor inside vsm(). It permits selected
levels of the factor—in this case Locations 3 and 4—to have their own
relative diagonal variance parameters within the random-effect
covariance. In the current parameterization the covariance factor is
normalized and vsm() supplies one product-level variance
scale, so the selected-level parameters describe variance ratios rather
than redundant absolute scales. The residual term similarly uses
dsm(Location) to allow location-specific residual
variances.
3) Using the vpredict calculator
Sometimes the user needs to calculate ratios or functions of specific
variance-covariance components and obtain the standard errors for such
parameters. Examples of these are the genetic correlations,
heritabilities, etc. Using the CPdata we will show how to estimate the
heritability and the standard error using the vpredict()
function that uses the delta method to come up with these parameters.
This can be extended for any linear combination of the variance
components.
3.1) Standar error for heritability
data(DT_cpdata, package="enhancer")
DT <- DT_cpdata
GT <- GT_cpdata
MP <- MP_cpdata
### look at the data
A <- A.mat(GT) # additive relationship matrix
Ai <- solve(A+ diag(1e-4, nrow(A),nrow(A)))
Ai[lower.tri(Ai)] <- t(Ai)[lower.tri(Ai)] # fill the lower triangular
Ai <- as(as(as( Ai,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Ai, "inverse")=TRUE

ans <- mmes(color~1,
            random=~vsm(ism(id),Gu=Ai),
            rcov=~units, nIters=10,
            data=DT, verbose = FALSE)
## Solver selected: cholmod
summary(ans)$varcomp## term parameter estimate StdError Zratio
## 1 vsm(ism(id), Gu = Ai) sigma2 0.005121546 0.0010577993 4.841699
## 2 vsm(ism(units)) sigma2 0.002743183 0.0003036588 9.033765
vpredict(ans, h2 ~ (V1) / ( V1+V2) )## Estimate SE
## h2 0.6512044 0.05322574The same can be used for multivariate models. Please check the
documentation of the vpredict function to see more
examples.
4) Half and full diallel designs (use of the overlay)
When breeders are looking for the best single-cross combinations, diallel designs have been by far the most used design in crops like maize. There are 4 types of diallel designs depending on whether reciprocal and self-crosses (omission of parents) are performed (full diallel with parents n^2; full diallel without parents n(n-1); half diallel with parents 1/2 * n(n+1); half diallel without parents 1/2 * n(n-1) ). In this example we will show a full diallel design (reciprocal crosses are performed) and half diallel designs (only one of the directions is performed).
In the first data set we show a full diallel among 40 lines from 2 heterotic groups, 20 in each. Therefore 400 possible hybrids are possible. We have pehnotypic data for 100 of them across 4 locations. We use the data available to fit a model of the form:
We estimate variance components for , and and use them to estimate heritability. Additionally BLUPs for GCA and SCA effects can be used to predict crosses.
data(DT_cornhybrids, package="enhancer")
DT <- DT_cornhybrids
DTi <- DTi_cornhybrids
GT <- GT_cornhybrids

modFD <- mmes(Yield~Location,
              random=~GCA1+GCA2+SCA,
              rcov=~units,
              data=DT, verbose = FALSE)
## Solver selected: ldlt
(suma <- summary(modFD)$varcomp)## term parameter estimate StdError Zratio
## 1 vsm(ism(GCA1)) sigma2 0.01286822 23.79880 5.407088e-04
## 2 vsm(ism(GCA2)) sigma2 7.37160220 21.04460 3.502847e-01
## 3 vsm(ism(SCA)) sigma2 187.57806322 40.79529 4.598032e+00
## 4 vsm(ism(units)) sigma2 221.14384357 18.14734 1.218602e+01
Vgca <- sum(suma[1:2,"estimate"])
Vsca <- suma[3,"estimate"]
Ve <- suma[4,"estimate"]
Va = 4*Vgca
Vd = 4*Vsca
Vg <- Va + Vd
(H2 <- Vg / (Vg + (Ve)) )
## [1] 0.7790758
(h2 <- Va / (Vg + (Ve)) )## [1] 0.02950855Don’t worry too much about the h2 value, the data was
simulated to be mainly dominance variance, therefore the Va
was simulated extremely small leading to such value of narrow sense
h2.
In the second data set we show a small half diallel with 7 parents
crossed in one direction. There are n(n-1)/2 possible crosses; 7(6)/2 =
21 unique crosses. Parents appear as males or females indistictly. Each
with two replications in a CRD. For a half diallel design a single GCA
variance component for both males and females can be estimated and an
SCA as well
(
and
respectively), and BLUPs for GCA and SCA of the parents can be
extracted. We will show first how to do so with the mmes()
function using the overlay() function. The specific model
here is:
##   rep geno male female     sugar
## 1   1   12    1      2 13.950509
## 2   2   12    1      2  9.756918
## 3   1   13    1      3 13.906355
## 4   2   13    1      3  9.119455
## 5   1   14    1      4  5.174483
## 6   2   14    1      4  8.452221
DT$femalef <- as.factor(DT$female)
DT$malef <- as.factor(DT$male)
DT$genof <- as.factor(DT$geno)
#### model using overlay
modh <- mmes(sugar~1,
             random=~vsm(ism(overlay(femalef,malef)) )
             + genof, data=DT, verbose = FALSE)
## Solver selected: ldlt
summary(modh)$varcomp## term parameter estimate StdError Zratio
## 1 vsm(ism(overlay(femalef, malef))) sigma2 5.509464 3.5792058 1.539298
## 2 vsm(ism(genof)) sigma2 1.811260 1.3614411 1.330399
## 3 vsm(ism(units)) sigma2 3.119529 0.9630436 3.239239Notice how the overlay() argument makes the overlap of
incidence matrices possible making sure that male and female are joint
into a single random effect.
5) Genomic selection: predicting mendelian sampling
In this section we will use wheat data from CIMMYT to show how genomic selection is performed. This is the case of prediction of specific individuals within a population. It basically uses a similar model of the form:
and takes advantage of the variance covariance matrix for the
genotype effect known as the additive relationship matrix (A) and
calculated using the A.mat function to establish
connections among all individuals and predict the BLUPs for individuals
that were not measured. The prediction accuracy depends on several
factors such as the heritability
(),
training population used (TP), size of TP, etc.
data(DT_wheat, package="enhancer")
DT <- DT_wheat
GT <- apply(GT_wheat,2,as.numeric)
rownames(GT) <- rownames(GT_wheat)

colnames(DT) <- paste0("X",1:ncol(DT))
DT <- as.data.frame(DT);DT$id <- as.factor(rownames(DT))
# select environment 1
K <- A.mat(GT) # additive relationship matrix
colnames(K) <- rownames(K) <- rownames(DT)
Ki <- solve(K+ diag(1e-4, nrow(K),nrow(K)))
Ki[lower.tri(Ki)] <- t(Ki)[lower.tri(Ki)] # fill the lower triangular
Ki <- as(as(as( Ki,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Ki, "inverse")=TRUE


# GBLUP pedigree-based approach
set.seed(12345)
y.trn <- DT
vv <- sample(rownames(DT),round(nrow(DT)/5))
y.trn[vv,"X1"] <- NA
head(y.trn)
## X1 X2 X3 X4 id
## 775 1.6716295 -1.72746986 -1.89028479 0.0509159 775
## 2166 -0.2527028 0.40952243 0.30938553 -1.7387588 2166
## 2167 NA -0.64862633 -0.79955921 -1.0535691 2167
## 2465 0.7854395 0.09394919 0.57046773 0.5517574 2465
## 3881 0.9983176 -0.28248062 1.61868192 -0.1142848 3881
## 3889 2.3360969 0.62647587 0.07353311 0.7195856 3889
## GBLUP with mmes
ans <- mmes(X1~1,
            random=~vsm(ism(id),Gu=Ki),
            rcov=~units,
            data=y.trn, verbose = FALSE) # kinship based
## Solver selected: cholmod
cor(ans$u[vv,] ,DT[vv,"X1"], use="complete")## [1] 0.5076072
## rrBLUP with mmer
ans2 <- mmer(X1~1,
             random=~vsr(list(GT)),
             rcov=~units, getPEV = TRUE,
             data=y.trn, verbose = FALSE) # kinship based
## This function has been deprecated. Please start using 'mmes' and its auxiliary functions. This function will be no longer maintained.
u <- GT %*% ans2$U$`u:GT`$X1 # BLUPs for individuals
rownames(u) <- rownames(GT)
cor(u[vv,],DT[vv,"X1"]) # same correlation
## [1] 0.5737681
# the same can be applied in multi-response models in GBLUP or rrBLUPThe two prediction formulations shown above use different
parameterizations. The GBLUP example fits genotype effects with the
sparse precision matrix Ki through mmes() and
vsm(). The rrBLUP example instead fits marker effects
through mmer() and vsr(list(GT)), so a
separate random effect is associated with each marker column. The older
buildGu=FALSE explanation does not apply to the code shown
here and is not part of the current mmes()
covariance-factor interface.
Marker effects can also be recovered from a GBLUP fit without
refitting, with meffects_mmes(). Passing the marker matrix
used in A.mat() reproduces how the relationship matrix was
built; blend accounts for a matrix of the form
,
and se = TRUE adds standard errors and back-solved GWAS
tests (Gualdron-Duarte et al. 2014):
6) Indirect genetic effects
General variance structures can be used to fit indirect genetic effects. Here, we use an example dataset to show how we can fit the variance and covariance components between two or more different random effects.
We first fit a direct genetic effects model:
data(DT_ige, package="enhancer")
DT <- DT_ige
Af <- A_ige
An <- A_ige

# Direct genetic effects model
modDGE <- mmes(trait ~ block,
               random = ~ focal,
               rcov = ~ units,
               data = DT, verbose=FALSE)
## Solver selected: ldlt
summary(modDGE)$varcomp## term parameter estimate StdError Zratio
## 1 vsm(ism(focal)) sigma2 19895.32 3108.3056 6.400695
## 2 vsm(ism(units)) sigma2 10133.63 477.7341 21.211860We now fit the indirect genetic effects model without covariance between DGE and IGE:
data(DT_ige, package="enhancer")
DT <- DT_ige
A <- A_ige

## Indirect genetic effects model
modIGE <- mmes(trait ~ block, dateWarning = FALSE,
               random = ~ focal + neighbour, verbose = FALSE,
               rcov = ~ units,
              data = DT)
## Solver selected: ldlt
summary(modIGE)$varcomp## term parameter estimate StdError Zratio
## 1 vsm(ism(focal)) sigma2 20553.755 3140.9324 6.543839
## 2 vsm(ism(neighbour)) sigma2 2928.598 604.5006 4.844656
## 3 vsm(ism(units)) sigma2 7299.466 363.8095 20.063980We now fit the indirect genetic effects model with covariance between
DGE and IGE for which we will use the strm() function
(covm() is its two-term special case):
modIGE <- mmes(trait ~ block, dateWarning = FALSE,
               random = ~ strm(dge = vsm(ism(focal)), ige = vsm(ism(neighbour))),
               rcov = ~ units, verbose = FALSE,
              data = DT)
## Solver selected: ldlt
summary(modIGE)$varcomp## term parameter
## 1 strm(dge = vsm(ism(focal)), ige = vsm(ism(neighbour))) variance[dge]
## 2 strm(dge = vsm(ism(focal)), ige = vsm(ism(neighbour))) covariance[ige,dge]
## 3 strm(dge = vsm(ism(focal)), ige = vsm(ism(neighbour))) variance[ige]
## 4 vsm(ism(units)) sigma2
## estimate StdError Zratio
## 1 21012.420 3204.1981 6.557778
## 2 -7468.722 1242.0673 -6.013138
## 3 2964.595 579.4758 5.115995
## 4 7297.577 358.2973 20.367381On top of that we can include a relationship matrix for the two random effects that are being forced to co-vary
Ai <- solve(A_ige + diag(1e-5, nrow(A_ige),nrow(A_ige) ))
attr(Ai, "inverse") <- TRUE
modIGE <- mmes(trait ~ block, dateWarning = FALSE,
               random = ~ strm(dge = vsm(ism(focal)), ige = vsm(ism(neighbour)), Gu = Ai),
               rcov = ~ units, verbose = FALSE,
              data = DT)
## Solver selected: cholmod
summary(modIGE)$varcomp## term
## 1 strm(dge = vsm(ism(focal)), ige = vsm(ism(neighbour)), Gu = Ai)
## 2 strm(dge = vsm(ism(focal)), ige = vsm(ism(neighbour)), Gu = Ai)
## 3 strm(dge = vsm(ism(focal)), ige = vsm(ism(neighbour)), Gu = Ai)
## 4 vsm(ism(units))
## parameter estimate StdError Zratio
## 1 variance[dge] 7804.992 1247.2282 6.257870
## 2 covariance[ige,dge] -2800.421 493.5832 -5.673655
## 3 variance[ige] 1139.836 242.9387 4.691865
## 4 sigma2 7315.269 356.3768 20.5267857) Genomic selection: single cross prediction
When doing prediction of single cross performance the phenotype can be dissected in three main components, the general combining abilities (GCA) and specific combining abilities (SCA). This can be expressed with the same model analyzed in the diallel experiment mentioned before:
with:
~ N(0, )
~ N(0, )
~ N(0, )
And we can specify the K matrices. The main difference between this model and the full and half diallel designs is the fact that this model will include variance covariance structures in each of the three random effects (GCA1, GCA2 and SCA) to be able to predict the crosses that have not ocurred yet. We will use the data published by Technow et al. (2015) to show how to do prediction of single crosses.
data(DT_technow, package="enhancer")
DT <- DT_technow

Md <- apply(Md_technow,2,as.numeric)
rownames(Md) <- rownames(Md_technow)
Mf <- apply(Mf_technow,2,as.numeric)
rownames(Mf) <- rownames(Mf_technow)

Md <- (Md*2) - 1
Mf <- (Mf*2) - 1
Ad <- A.mat(Md)
Af <- A.mat(Mf)
Adi <- solve(Ad + diag(1e-4,ncol(Ad),ncol(Ad)))
Adi[lower.tri(Adi)] <- t(Adi)[lower.tri(Adi)] # fill the lower triangular
Adi <- as(as(as( Adi,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Adi, 'inverse')=TRUE
Afi <- solve(Af + diag(1e-4,ncol(Af),ncol(Af)))
Afi[lower.tri(Afi)] <- t(Afi)[lower.tri(Afi)] # fill the lower triangular
Afi <- as(as(as( Afi,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Afi, 'inverse')=TRUE
# RUN THE PREDICTION MODEL
y.trn <- DT
vv1 <- which(!is.na(DT$GY))
vv2 <- sample(vv1, 100)
y.trn[vv2,"GY"] <- NA
anss2 <- mmes(GY~1,  henderson=TRUE,
              random=~vsm(ism(dent),Gu=Adi) + vsm(ism(flint),Gu=Afi),
              rcov=~units, nIters=15,
              data=y.trn, verbose = FALSE)
## Solver selected: cholmod
summary(anss2)$varcomp## term parameter estimate StdError Zratio
## 1 vsm(ism(dent), Gu = Adi) sigma2 16.06045 2.6426373 6.077434
## 2 vsm(ism(flint), Gu = Afi) sigma2 11.41698 2.2418799 5.092592
## 3 vsm(ism(units)) sigma2 16.81829 0.7742368 21.722407
# zu1 <- model.matrix(~dent-1,y.trn) %*% anss2$uList$`vsm(ism(dent), Gu = Adi)`
# zu2 <- model.matrix(~flint-1,y.trn) %*% anss2$uList$`vsm(ism(flint), Gu = Afi)`
# u <- zu1+zu2+as.vector(anss2$b)
# cor(u[vv2,], DT$GY[vv2])
In the previous model we only used the GCA effects (GCA1 and GCA2) for practicity, altough it’s been shown that the SCA effect doesn’t actually help that much in increasing prediction accuracy, but does increase a lot the computation intensity required since the variance covariance matrix for SCA is the kronecker product of the variance covariance matrices for the GCA effects, resulting in a 10578 x 10578 matrix that increases in a very intensive manner the computation required.
A model without covariance structures would show that the SCA variance component is insignificant compared to the GCA effects. This is why including the third random effect doesn’t increase the prediction accuracy.
8) Multivariate genetic models and genetic correlations
Multivariate mixed models are useful for estimating genetic variances
and covariances among traits. The example below represents two traits
(color and Yield) in long format, with a
single response column and a factor identifying the trait. This makes
trait a covariance dimension that can be included explicitly in
vsm(). The random term
vsm(usm(trait), ism(id), Gu=Ai) represents the genotype
covariance as a Kronecker product of an unstructured trait covariance
factor and the genotype relationship structure, while
vsm(dsm(trait), ism(units)) allows trait-specific residual
variances with zero residual covariance between traits.
# data(DT_cpdata, package="enhancer")
# DT <- DT_cpdata
# GT <- GT_cpdata
# MP <- MP_cpdata
# traits <- c("color","Yield")
# DT[,traits] <- apply(DT[,traits],2,scale)
# DTL <- reshape(DT[,c("id", traits)],
#                idvar = c("id"),
#                varying = traits,
#                v.names = "value", direction = "long",
#                timevar = "trait", times = traits )
# DTL <- DTL[with(DTL, order(trait)), ]
# head(DTL)
#
# A <- A.mat(GT) # additive relationship matrix
# # if using mmes=TRUE you need to provide the inverse
# Ai <- solve(A + diag(1e-4,ncol(A),ncol(A)))
# Ai[lower.tri(Ai)] <- t(Ai)[lower.tri(Ai)] # fill the lower triangular
# Ai <- as(as(as( Ai,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
# attr(Ai, 'inverse')=TRUE
# #### be patient this model is heavier
# ansm <- mmes( value ~ trait, # henderson=TRUE,
#                random=~ vsm(usm(trait), ism(id), Gu=Ai), # Ai if henderson
#                rcov=~ vsm(dsm(trait), ism(units)),
#                data=DTL)
# cov2cor(ansm$theta[[1]])
For wide data, stackTraits() creates the long response
and an explicit record key. Use that key as the final residual incidence
when traits measured on the same experimental unit should have
correlated errors; covmatrix_mmes() returns the fitted
covariance, correlation and their standard errors.
# DTL <- stackTraits(DT, traits = c("color", "Yield"), keep = "id")
# ansm <- mmes(value ~ trait,
#              random = ~ vsm(usm(trait), ism(id), Gu = Ai),
#              rcov = ~ vsm(usm(trait), ism(record)), data = DTL)
# covmatrix_mmes(ansm, 1)$correlation  # genetic correlation
# covmatrix_mmes(ansm, 2)$correlation  # residual correlation
Mixed-family traits are also supported through
familym(). For example, a binary disease score and a
Gaussian yield can be fitted jointly with an unstructured genetic
covariance. The residual covariance uses
corgm(trait, variance="heterogeneous") so that the fixed
binomial residual variance and the estimated Gaussian residual variance
can coexist; see the familym() and corgm()
examples for a complete reproducible fit.
Other examples of multi-trait models can be found in the documentation of the rice dataset (DT_rice) and in the example dataset (DT_example).
9) Bivariate model with repeated records
We first mimic the availability of 2 traits (TRAIT) with repeated records across several days (X) for a response variable (Y).
##     SUBJECT X          Y Xf
## 1.1       1 1 -0.7432795  1
## 2.1       2 1 -0.6669945  1
## 3.1       3 1 -4.2802751  1
## 4.1       4 1  4.1092149  1
## 5.1       5 1 -3.0317213  1
## 6.1       6 1  1.3506577  1
DT$SUBJECT <- paste("s",DT$SUBJECT,sep="_")
DT1 <- DT2 <- DT
DT1$TRAIT <- "T1"
DT2$TRAIT <- "T2"
DT2$Y <- sample(DT2$Y)
DTC <- rbind(DT1,DT2)
Now we fit an unstructured model for a legendre polynomial with two traits and a diagonal model for the residual.
#
# library(orthopolynom)
#
# Z <- with(DTC, dsm(leg(X,1)) )$Z
# for(i in 1:ncol(Z)){DTC[,colnames(Z)[i]] <- Z[,i]}
#
# X <- with(DTC, dsm(TRAIT) )$Z
# for(i in 1:ncol(X)){DTC[,colnames(X)[i]] <- X[,i]}
#
# A <- diag(length(unique(DTC$SUBJECT)))
# rownames(A) <- colnames(A) <- unique(DTC$SUBJECT)
# Ai <- solve(A + diag(1e-4,ncol(A),ncol(A)))
# Ai[lower.tri(Ai)] <- t(Ai)[lower.tri(Ai)] # fill the lower triangular
# Ai <- as(as(as( Ai,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
# attr(Ai, 'inverse')=TRUE
# ##
# M <- model.matrix(~ T1:leg0 + T1:leg1 + T2:leg0 + T2:leg1 - 1 , data=DTC)
# mRR2b<-mmes(Y ~ Xf,
#             random=~ vsm( usm( M ) ,  ism(SUBJECT) , Gu = Ai),
#             rcov = ~ vsm( dsm(TRAIT), ism(units) ),
#             nIters = 10, verbose = FALSE,
#             data=DTC)
# summary(mRR2b)$varcomp
SECTION 3: Special topics in Quantitative genetics
1) Partitioned model
Marker-effect BLUPs can be recovered from an equivalent GBLUP parameterization by exploiting the relationship between the marker matrix , the genomic covariance , and the corresponding genotype BLUPs. The example below fits the marker model directly and then fits a partitioned GBLUP model based on . Marker effects are recovered from genotype effects with the linear transformation , using the regularized inverse constructed in the example. This illustrates the algebraic equivalence of the two parameterizations under the covariance scaling used here.
library(sommer)
data("DT_cpdata", package="enhancer")
DT <- DT_cpdata
M <- GT_cpdata

################
# MARKER MODEL
################
mix.marker <- mmer(Yield~1,
                   random=~Rowf+vsr(list(M)),
                   rcov=~units,data=DT,
                   verbose = FALSE)
## This function has been deprecated. Please start using 'mmes' and its auxiliary functions. This function will be no longer maintained.
me.marker <- mix.marker$U$`u:M`$Yield

################
# PARTITIONED GBLUP MODEL
################

MMT <-tcrossprod(M) ## MM' = additive relationship matrix
MMTinv<-solve(MMT + diag(1e-4, nrow(MMT), nrow(MMT))) ## inverse
MTMMTinv<-t(M)%*%MMTinv # M' %*% (M'M)-
MMTinv <- as(as(as( MMTinv,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(MMTinv, 'inverse')=TRUE

mix.part <- mmes(Yield~1, nIters = 20,
                 random=~Rowf+vsm(ism(id), Gu=MMTinv),
                 rcov=~units,data=DT,
                 verbose = FALSE)
## Solver selected: cholmod
#convert BLUPs to marker effects me=M'(M'M)- u
me.part<-MTMMTinv%*%matrix(mix.part$uList$`vsm(ism(id), Gu = MMTinv`,ncol=1)

# compare marker effects between both models
plot(me.marker,me.part)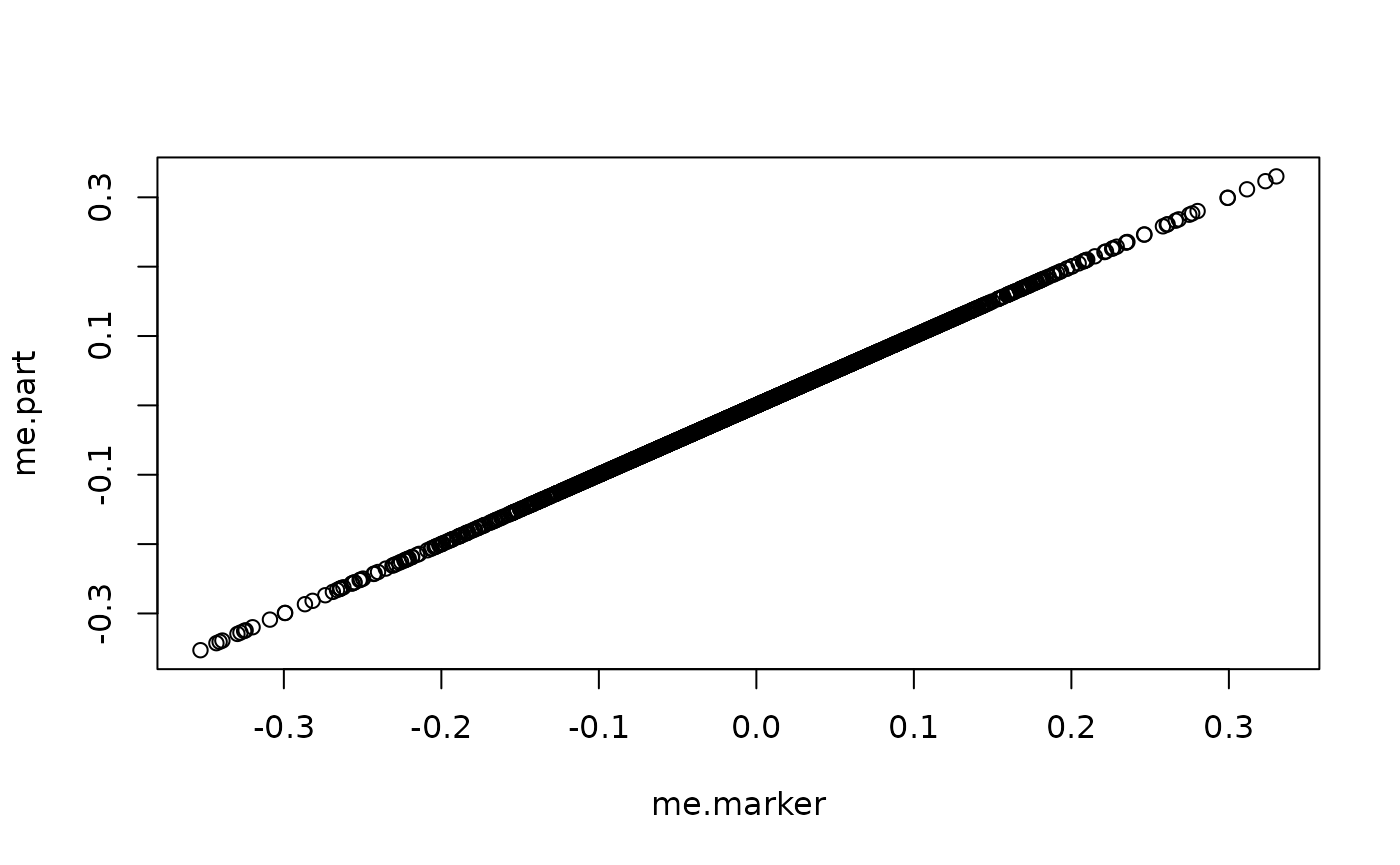
Under the covariance construction and regularization used in this example, the two parameterizations produce the corresponding marker-effect predictions through the stated linear transformation. Their relative computational cost depends on the numbers of records, genotypes and markers and on the solver formulation; therefore the partitioned form should not be assumed to be universally faster.
2) UDU’ decomposition
An eigendecomposition of a symmetric relationship matrix can be
written
,
with orthogonal eigenvectors
and diagonal eigenvalue matrix
.
Premultiplying the model by
rotates the observations and design matrices into this eigenbasis, so
the relationship component becomes diagonal. The mmes()
interface performs this transformation internally when
rotation=TRUE is supplied to the relationship
vsm() term; users should provide the named relationship
precision matrix through Gu, just as in an
ordinary mmes() fit.
data("DT_wheat", package="enhancer")
rownames(GT_wheat) <- rownames(DT_wheat)
GT <- apply(GT_wheat,2,as.numeric)
rownames(GT) <- rownames(GT_wheat)
A <- A.mat(GT)
Ai <- solve(A + diag(1e-5, nrow(A)))
Ai[lower.tri(Ai)] <- t(Ai)[lower.tri(Ai)] # fill the lower triangular
Ai <- as(as(as(Ai, "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Ai, "inverse") <- TRUE
isSymmetric(Ai)
## [1] TRUE
# One complete observation per relationship level gives a balanced example.
DTn <- data.frame(
  id=rownames(A),
  y=as.numeric(DT_wheat[,1])
)

model_regular <- mmes(
  y~1,
  random=~vsm(ism(id), Gu=Ai),
  rcov=~units, data=DTn, verbose=FALSE
)
## Solver selected: cholmod
# Henderson MME formulation with eigenbasis random coefficients.
model_rotation_h <- mmes(
  y~1,
  random=~vsm(ism(id), Gu=Ai, rotation=TRUE),
  rcov=~units, data=DTn, henderson=TRUE, verbose=FALSE
)
## Solver selected: ldlt
# Lee--van der Werf direct observation-covariance formulation.
model_rotation_d <- mmes(
  y~1,
  random=~vsm(ism(id), Gu=Ai, rotation=TRUE),
  rcov=~units, data=DTn, henderson=FALSE, verbose=FALSE
)
## Engine selected: direct inversion (henderson=FALSE)
model_regular$covParNative## term factor section parameter estimate StdError Zratio
## 1 vsm(ism(id), Gu = Ai) sigma2 <NA> sigma2 0.2090168 0.04287193 4.875377
## 2 vsm(ism(units)) sigma2 <NA> sigma2 0.6376732 0.04619909 13.802722
model_rotation_h$covParNative## term factor section parameter estimate
## 1 vsm(ism(id), Gu = Ai, rotation = TRUE) sigma2 <NA> sigma2 0.2090168
## 2 vsm(ism(units)) sigma2 <NA> sigma2 0.6376732
## StdError Zratio
## 1 0.04287193 4.875377
## 2 0.04619909 13.802722
model_rotation_d$covParNative## term factor section parameter estimate
## 1 vsm(ism(id), Gu = Ai, rotation = TRUE) sigma2 <NA> sigma2 0.2090168
## 2 vsm(ism(units)) sigma2 <NA> sigma2 0.6376732
## StdError Zratio
## 1 0.04287193 4.875377
## 2 0.04619909 13.802722
plot(model_rotation_h$bu[,1], model_regular$bu[,1])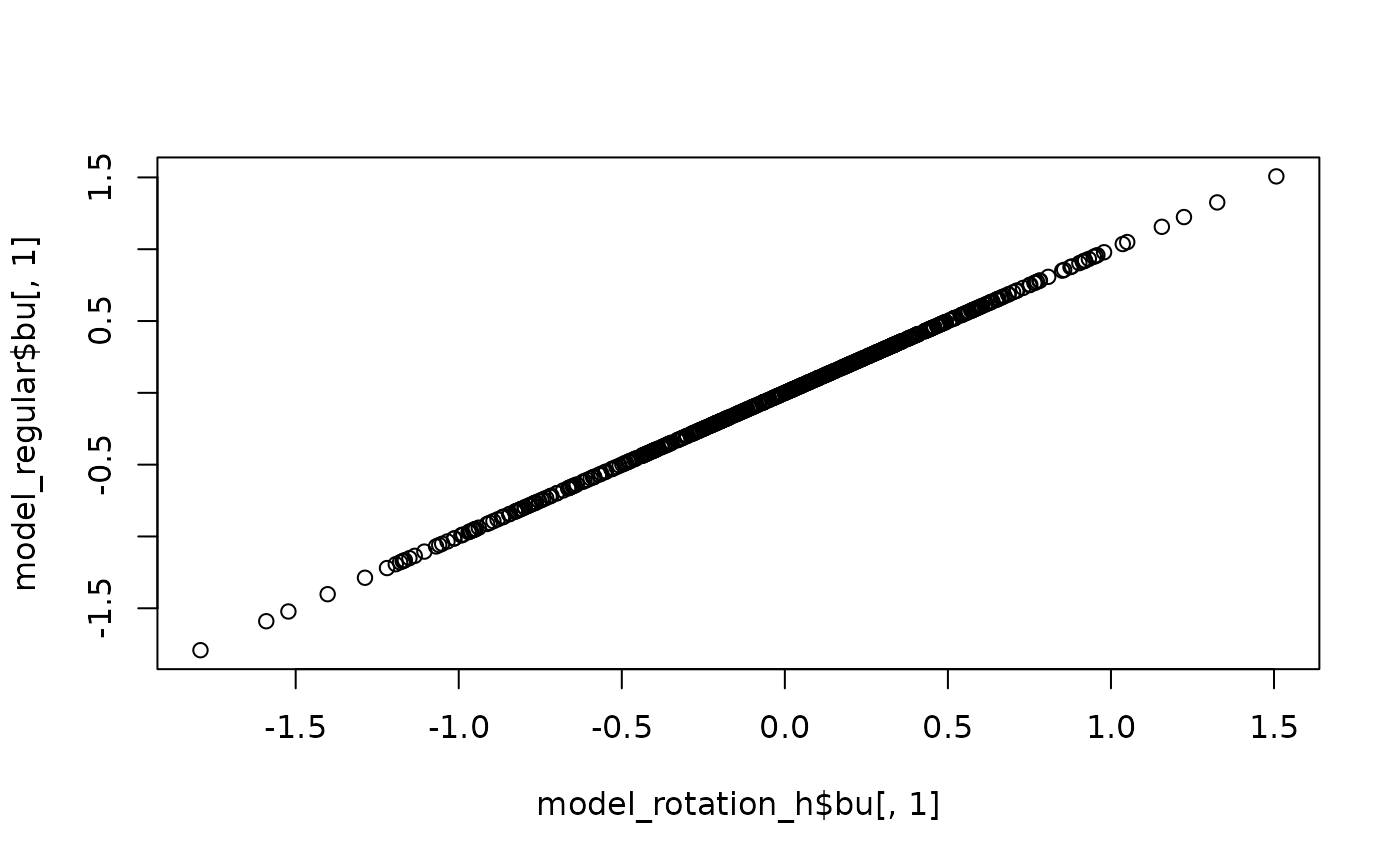
plot(model_rotation_d$bu[,1], model_regular$bu[,1])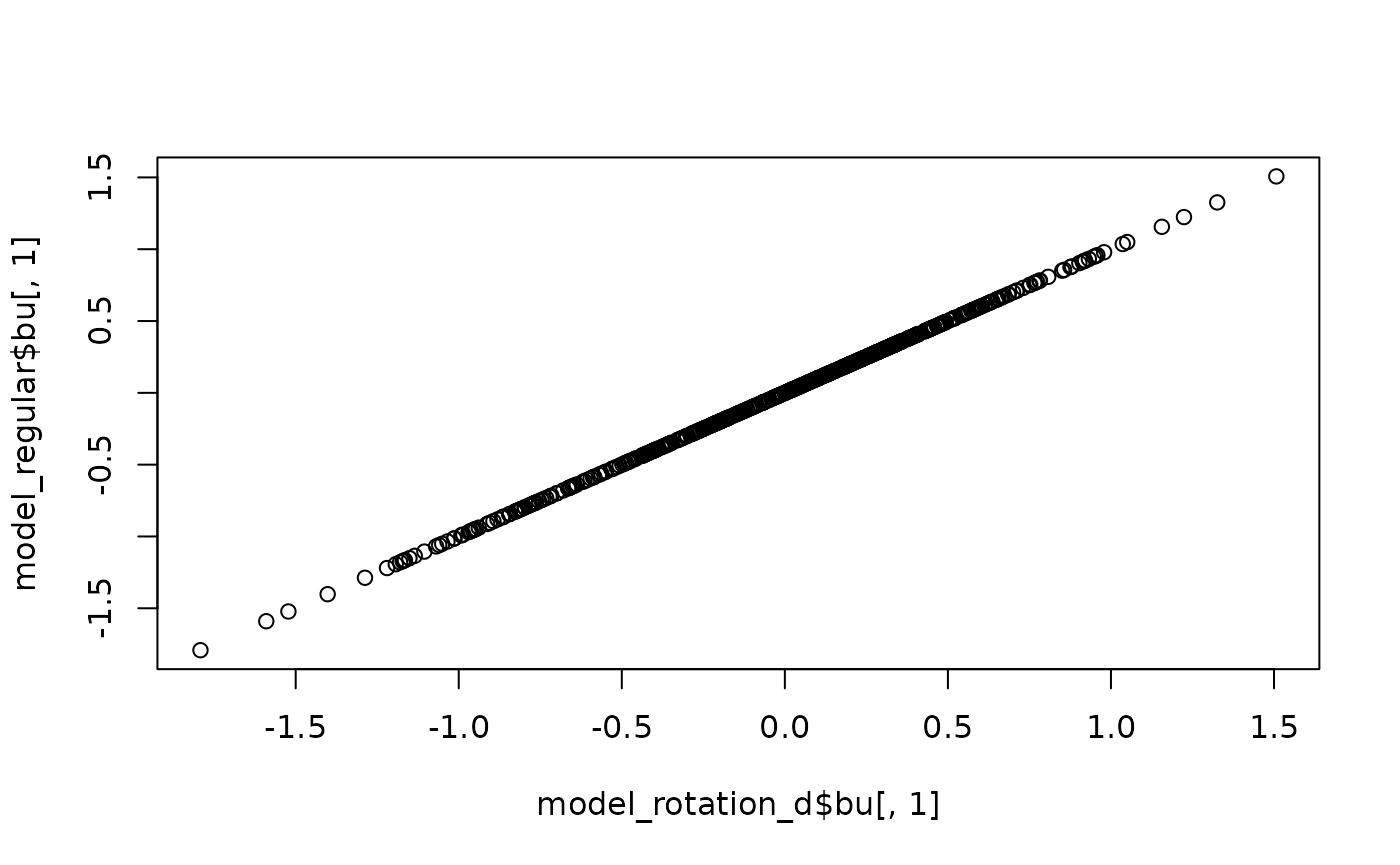
The transformed and untransformed formulations are algebraically
equivalent under the rotation assumptions. The current implementation
accepts one rotated relationship term in a complete balanced Gaussian
model and computeCi=0 during fitting. Residual structures
are supported when they are rotation invariant, i.e. when residuals may
covary across rotation blocks such as traits or environments but are
independent and identically structured across the levels of the rotated
term:
.
Examples are rcov=~units,
rcov=~vsm(dsm(env), ism(units)), and
rcov=~vsm(usm(trait), ism(units)). Residual structures
correlating observations of different levels (e.g., ar1m()
or maternm() over plots), residual variances differing
among levels, and W matrices that are not diagonal with a
constant weight within each rotation block are not invariant and are
rejected. With henderson=TRUE, mmes() uses
diagonal relationship precision in the eigen-coefficient basis. With
henderson=FALSE, it uses the Lee–van der Werf transformed
observation-covariance formulation. The relative computational benefit
depends on model dimensions and sparsity.
Another example of how usefult this can be is in the multi-trait models:
data("DT_wheat", package="enhancer")
rownames(GT_wheat) <- rownames(DT_wheat)
GT <- apply(GT_wheat,2,as.numeric)
rownames(GT) <- rownames(GT_wheat)
A <- A.mat(GT)
Ai <- solve(A + diag(1e-5, nrow(A)))
Ai[lower.tri(Ai)] <- t(Ai)[lower.tri(Ai)] # fill the lower triangular
Ai <- as(as(as(Ai, "dMatrix"), "generalMatrix"), "CsparseMatrix")
attr(Ai, "inverse") <- TRUE
isSymmetric(Ai)
## [1] TRUE
# One complete observation per relationship level gives a balanced example.
data(DT_wheat)
DT <- DT_wheat
GT <- apply(GT_wheat,2,as.numeric)
rownames(GT) <- rownames(GT_wheat)
DT <- data.frame(pheno=as.vector(DT),
                 env=as.factor(paste0("e", sort(rep(1:4,nrow(DT))))),
                 id=rep(rownames(DT),4))

# Henderson MME formulation with eigenbasis random coefficients.
model_rotation_h <- mmes(
  pheno~1,
  random=~vsm(usm(env),ism(id), Gu=Ai, rotation=TRUE),
  rcov=~vsm(dsm(env),ism(units)), data=DT, henderson=TRUE, verbose=FALSE
)
## Solver selected: ldlt
# genetic correlation
cov2cor(model_rotation_h$theta[[1]])
## [,1] [,2] [,3] [,4]
## [1,] 1.0000000 -0.2051858 -0.2914906 -0.3932007
## [2,] -0.2051858 1.0000000 0.9938324 0.7959839
## [3,] -0.2914906 0.9938324 1.0000000 0.8486331
## [4,] -0.3932007 0.7959839 0.8486331 1.00000003) Mating designs
Estimating variance components has been a topic of interest for the breeding community for a long time. Here we show how to calculate additive and dominance variance using the North Carolina Design I (Nested design) and North Carolina Design II (Factorial design) using the classical Expected Mean Squares method and the REML methods from sommer and how these two are equivalent.
North Carolina Design I (Nested design)
data(DT_expdesigns, package="enhancer")
DT <- DT_expdesigns$car1
DT <- aggregate(yield~set+male+female+rep, data=DT, FUN = mean)
DT$setf <- as.factor(DT$set)
DT$repf <- as.factor(DT$rep)
DT$malef <- as.factor(DT$male)
DT$femalef <- as.factor(DT$female)
# lattice::levelplot(yield~male * malef:femalef|set, data=DT, main="NC design I")
##############################
## Expected Mean Square method
##############################
mix1 <- lm(yield~ setf + setf:repf + femalef:malef:setf + malef:setf, data=DT)
MS <- anova(mix1); MS
## Analysis of Variance Table
##
## Response: yield
## Df Sum Sq Mean Sq F value Pr(>F)
## setf 1 0.1780 0.17796 1.6646 0.226012
## setf:repf 2 0.9965 0.49824 4.6605 0.037141 *
## setf:malef 4 7.3904 1.84759 17.2822 0.000173 ***
## setf:femalef:malef 6 1.6083 0.26806 2.5074 0.095575 .
## Residuals 10 1.0691 0.10691
## ---
## Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
ms1 <- MS["setf:malef","Mean Sq"]
ms2 <- MS["setf:femalef:malef","Mean Sq"]
mse <- MS["Residuals","Mean Sq"]
nrep=2
nfem=2
Vfm <- (ms2-mse)/nrep
Vm <- (ms1-ms2)/(nrep*nfem)

## Calculate Va and Vd
Va=4*Vm # assuming no inbreeding (4/(1+F))
Vd=4*(Vfm-Vm) # assuming no inbreeding(4/(1+F)^2)
Vg=c(Va,Vd); names(Vg) <- c("Va","Vd"); Vg
## Va Vd
## 1.579537 -1.257241
##############################
## REML method
##############################
mix2 <- mmes(yield~ setf + setf:repf,
            random=~femalef:malef:setf + malef:setf,
            data=DT, verbose = FALSE)
## Solver selected: ldlt
vc <- summary(mix2)$varcomp; vc## term parameter estimate StdError Zratio
## 1 vsm(ism(femalef:malef:setf)) sigma2 0.08097714 0.08121685 0.9970485
## 2 vsm(ism(malef:setf)) sigma2 0.39424094 0.32839051 1.2005248
## 3 vsm(ism(units)) sigma2 0.10670010 0.04767145 2.2382391
Vfm <- vc[1,"estimate"]
Vm <- vc[2,"estimate"]

## Calculate Va and Vd
Va=4*Vm # assuming no inbreeding (4/(1+F))
Vd=4*(Vfm-Vm) # assuming no inbreeding(4/(1+F)^2)
Vg=c(Va,Vd); names(Vg) <- c("Va","Vd"); Vg
## Va Vd
## 1.576964 -1.253055As can be seen the REML method is easier than manipulating the MS and we arrive to the same results.
North Carolina Design II (Factorial design)
DT <- DT_expdesigns$car2
DT <- aggregate(yield~set+male+female+rep, data=DT, FUN = mean)
DT$setf <- as.factor(DT$set)
DT$repf <- as.factor(DT$rep)
DT$malef <- as.factor(DT$male)
DT$femalef <- as.factor(DT$female)
#levelplot(yield~male*female|set, data=DT, main="NC desing II")
head(DT)
## set male female rep yield setf repf malef femalef
## 1 1 1 1 1 831.03 1 1 1 1
## 2 1 2 1 1 1046.55 1 1 2 1
## 3 1 3 1 1 853.33 1 1 3 1
## 4 1 4 1 1 940.00 1 1 4 1
## 5 1 5 1 1 802.00 1 1 5 1
## 6 1 1 2 1 625.93 1 1 1 2
N=with(DT,table(female, male, set))
nmale=length(which(N[1,,1] > 0))
nfemale=length(which(N[,1,1] > 0))
nrep=table(N[,,1])
nrep=as.numeric(names(nrep[which(names(nrep) !=0)]))

##############################
## Expected Mean Square method
##############################

mix1 <- lm(yield~ setf + setf:repf +
             femalef:malef:setf + malef:setf + femalef:setf, data=DT)
MS <- anova(mix1); MS
## Analysis of Variance Table
##
## Response: yield
## Df Sum Sq Mean Sq F value Pr(>F)
## setf 1 847836 847836 45.6296 1.097e-09 ***
## setf:repf 4 144345 36086 1.9421 0.109652
## setf:malef 8 861053 107632 5.7926 5.032e-06 ***
## setf:femalef 8 527023 65878 3.5455 0.001227 **
## setf:femalef:malef 32 807267 25227 1.3577 0.129527
## Residuals 96 1783762 18581
## ---
## Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
ms1 <- MS["setf:malef","Mean Sq"]
ms2 <- MS["setf:femalef","Mean Sq"]
ms3 <- MS["setf:femalef:malef","Mean Sq"]
mse <- MS["Residuals","Mean Sq"]
nrep=length(unique(DT$rep))
nfem=length(unique(DT$female))
nmal=length(unique(DT$male))
Vfm <- (ms3-mse)/nrep;
Vf <- (ms2-ms3)/(nrep*nmale);
Vm <- (ms1-ms3)/(nrep*nfemale);

Va=4*Vm; # assuming no inbreeding (4/(1+F))
Va=4*Vf; # assuming no inbreeding (4/(1+F))
Vd=4*(Vfm); # assuming no inbreeding(4/(1+F)^2)
Vg=c(Va,Vd); names(Vg) <- c("Va","Vd"); Vg
## Va Vd
## 10840.192 8861.659
##############################
## REML method
##############################

mix2 <- mmes(yield~ setf + setf:repf ,
            random=~femalef:malef:setf + malef:setf + femalef:setf,
            data=DT, verbose = FALSE)
## Solver selected: ldlt
vc <- summary(mix2)$varcomp; vc## term parameter estimate StdError Zratio
## 1 vsm(ism(femalef:malef:setf)) sigma2 2222.783 2285.897 0.9723898
## 2 vsm(ism(malef:setf)) sigma2 5491.326 3611.317 1.5205881
## 3 vsm(ism(femalef:setf)) sigma2 2707.749 2234.904 1.2115729
## 4 vsm(ism(units)) sigma2 18573.258 2680.270 6.9296208
Vfm <- vc[1,"estimate"]
Vm <- vc[2,"estimate"]
Vf <- vc[3,"estimate"]

Va=4*Vm; # assuming no inbreeding (4/(1+F))
Va=4*Vf; # assuming no inbreeding (4/(1+F))
Vd=4*(Vfm); # assuming no inbreeding(4/(1+F)^2)
Vg=c(Va,Vd); names(Vg) <- c("Va","Vd"); Vg
## Va Vd
## 10831.00 8891.13As can be seen, the REML method is easier than manipulating the MS and we arrive to the same results.
4) GWAS by GBLUP
Gualdron-Duarte et al. (2014) and Bernal-Rubio et al. (2016) proved that in (SingleStep)GBLUP or RRBLUP/SNP-BLUP, dividing the estimate of the marker effect by its standard error is mathematically equivalent to fixed regression EMMAX GWAS, even if markers are estimated as random effects in GBLUP and as fixed effects in EMMAX. That way fitting a GBLUP model is enough to perform GWAS for additive and on-additive effects.
Let us use the DT_cpdata dataset to explore the GWAS by GBLUP method
data(DT_cpdata, package="enhancer")
DT <- DT_cpdata
GT <- GT_cpdata[,1:200]
MP <- MP_cpdata
#### create the variance-covariance matrix
A <- A.mat(GT) # additive relationship matrix
n <- nrow(DT) # to be used for degrees of freedom
k <- 1 # to be used for degrees of freedom (number of levels in fixed effects)
First we fit a regular GWAS/EMMAX using the GWAS function available in sommer that first calculates variance components and then fits a regression marker by marker as a fixed effect.
###########################
#### Regular GWAS/EMMAX approach
###########################
# mix2 <- GWAS(color~1,
#              random=~vsm(ism(id), Gu=A) + Rowf + Colf,
#              rcov=~units, M=GT, gTerm = "u:id",
#              verbose = FALSE,
#              data=DT)
To compare EMMAX to the approach proposed by Gualdron-Duarte et al. (2014) and Bernal-Rubio et al. (2016) we will start fitting an RRBLUP/SNP-BLUP model to show that the estimate of the marker effect by its standard error is mathematically equivalent to fixed regression EMMAX GWAS.
# ###########################
# #### GWAS by RRBLUP approach
# ###########################
# Z <- GT[as.character(DT$id),]
# mixRRBLUP <- mmer(Yield~1,
#               random=~vsr(list(Z)) + Rowf + Colf,
#               rcov=~units, nIters=10,
#               verbose = FALSE,
#               data=DT)
#
# a <- mixRRBLUP$U$`u:Z`$Yield
# se.a <- sqrt( diag(kronecker(diag(ncol(Z)),mixRRBLUP$sigma$`u:Z`) - mixRRBLUP$PevU$`u:Z`$Yield ) ) # SE of marker effects
# t.stat <- a/se.a # t-statistic
# pvalRRBLUP <- dt(t.stat,df=n-k-1) # -log10(pval)
Instead of fitting the RRBLUP/SNP-BLUP model we can fit a GBLUP model which is less computationally demanding and recover marker effects and their standard errors from the genotype effects.
# ###########################
# #### GWAS by GBLUP approach
# ###########################
# M<- GT
# MMT <-tcrossprod(M) ## MM' = additive relationship matrix
# MMTinv<-solve(MMT + diag(1e-4, ncol(MMT), ncol(MMT))) ## inverse of MM'
# MTMMTinv<-t(M)%*%MMTinv # M' %*% (M'M)-
# MMTinv <- as(as(as( MMTinv,  "dMatrix"), "generalMatrix"), "CsparseMatrix")
# attr(MMTinv, 'inverse')=TRUE
#
# mixGBLUP <- mmes(Yield~1,
#              random=~vsm(ism(id), Gu=MMTinv) + Rowf + Colf,
#              rcov=~units, nIters=25,
#              verbose = T, computeCi = 2,
#              data=DT)
# a.from.g <-MTMMTinv%*%matrix(mixGBLUP$uList$`vsm(ism(id), Gu = MMTinv`,ncol=1)
# start=mixGBLUP$partitions[[1]][1]
# end=mixGBLUP$partitions[[1]][2]
# var.g <- kronecker(MMT,mixGBLUP$theta[[1]]) - mixGBLUP$Ci[start:end,start:end]
# var.a.from.g <- t(M)%*%MMTinv%*% (var.g) %*% t(MMTinv)%*%M
# se.a.from.g <- sqrt(diag(var.a.from.g))
# t.stat.from.g <- a.from.g/se.a.from.g # t-statistic
# pvalGBLUP <- dt(t.stat.from.g,df=n-k-1) # -log10(pval)
Now we can look at the p-values coming from the 3 approaches to indeed show that results are equivalent.
###########################
#### Compare results
###########################
# plot(mix2$scores[,1], main="GWAS")
# plot(-log(pvalRRBLUP), main="GWAS by RRBLUP/SNP-BLUP")
# plot(-log(pvalGBLUP), main="GWAS by GBLUP")
Final remarks
Keep in mind that the current mmes() solver uses
Henderson’s mixed model equations with sparse Average Information REML;
it is not the former dense direct-inversion implementation. Its
performance depends strongly on sparsity, the number and structure of
random effects, fill-in in the sparse factorization, and the covariance
models being fitted. The complementary mmer()
marginal-covariance formulation remains useful for models whose
dimensions or covariance representation favor observation-space
calculations. Thus solver choice should be based on the structure of the
particular problem rather than only on whether the number of records
exceeds the number of coefficients.
Literature
Covarrubias-Pazaran G. 2016. Genome assisted prediction of quantitative traits using the R package sommer. PLoS ONE 11(6):1-15.
Covarrubias-Pazaran G. 2018. Software update: Moving the R package sommer to multivariate mixed models for genome-assisted prediction. doi: https://doi.org/10.1101/354639
Bernardo Rex. 2010. Breeding for quantitative traits in plants. Second edition. Stemma Press. 390 pp.
Gilmour et al. 1995. Average Information REML: An efficient algorithm for variance parameter estimation in linear mixed models. Biometrics 51(4):1440-1450.
Henderson C.R. 1975. Best Linear Unbiased Estimation and Prediction under a Selection Model. Biometrics vol. 31(2):423-447.
Kang et al. 2008. Efficient control of population structure in model organism association mapping. Genetics 178:1709-1723.
Lee, D.-J., Durban, M., and Eilers, P.H.C. (2013). Efficient two-dimensional smoothing with P-spline ANOVA mixed models and nested bases. Computational Statistics and Data Analysis, 61, 22 - 37.
Lee, S.H. and van der Werf, J.H.J. 2016. MTG2: An efficient algorithm for multivariate linear mixed model analysis based on genomic information. Bioinformatics 32(9):1420-1422. doi:10.1093/bioinformatics/btw012.
Maier et al. 2015. Joint analysis of psychiatric disorders increases accuracy of risk prediction for schizophrenia, bipolar disorder, and major depressive disorder. Am J Hum Genet; 96(2):283-294.
Rodriguez-Alvarez, Maria Xose, et al. Correcting for spatial heterogeneity in plant breeding experiments with P-splines. Spatial Statistics 23 (2018): 52-71.
Searle. 1993. Applying the EM algorithm to calculating ML and REML estimates of variance components. Paper invited for the 1993 American Statistical Association Meeting, San Francisco.
Yu et al. 2006. A unified mixed-model method for association mapping that accounts for multiple levels of relatedness. Genetics 38:203-208.
Tunnicliffe W. 1989. On the use of marginal likelihood in time series model estimation. JRSS 51(1):15-27.